Apèsi
Sa a se yon vèsyon 90 minit ki refè yon emisyon an dirèk sou entèlijans atifisyèl ki te fèt an fevriye 2026, ki bati apati transkripsyon an epi ki elaji ak materyèl sou dènye avansman yo ki te pwomèt men ki te koupe. Emisyon an kouvri 90 ane istwa AI — depi atik fondamantal Alan Turing te ekri an 1936 la rive nan modèl ki pi avanse yo jodi a — epi li fini sou sa Konte Miami-Dade dwe fè pou l prepare.
Chak segman ki anba a gen yon dire objektif, moman ouvèti a, pwen pou pale yo nan lòd, ak yon tranzisyon pou antre nan segman k ap vini an. Li pwen pou pale yo tankou yon gid referans, pa tankou yon tèks pou resite. Prezantasyon an fèt sou fòm konvèsasyon. Kenbe enèji a dirèk ak vokabilè a presi — sa a se vrè travay teknik ki eksplike yon fason klè.
Kijan pou itilize dokiman sa a
De bagay pou nou konnen si n ap li sa a olye pou nou gade emisyon an:
- Premye 55 minit yo repase emisyon fevriye a nan yon ritm pi sere; dènye 35 minit yo se nouvo materyèl ki kouvri AGI, sipèentèlijans, aliyman, travay, ak preparasyon Miami-Dade.
- De amelyorasyon pwodiksyon pou yon nouvo difizyon: Mete tout ti zafè òganizasyon yo (piblikasyon sou rezo sosyal, envitasyon pou ko-animatè) nan premye 60 segonn yo pou yo pa koupe istwa Turing nan. Mete yon limit tan ki fèm sou Segman 2–8 yo pou ou rive nan materyèl sou dènye avansman yo ak 35 minit an rezèv.
Plan emisyon an (90 minit)
Premye 55 minit yo: Emisyon orijinal la, ak yon nouvo ritm
Dènye 35 minit yo: Nouvo materyèl
- 0:00 – Segman 1: Ouvèti dirèk: bibliyotèk 1936 la (4 min)
- 0:04 – Segman 2: Fondasyon yo: Church, Turing, pwoblèm arè a (7 min)
- 0:11 – Segman 3: Dartmouth 1956, sistèm ekspè, ivè AI yo (6 min)
- 0:17 – Segman 4: Depi backprop rive nan ImageNet: machin nan aprann wè (7 min)
- 0:24 – Segman 5: Revolisyon transformer yo (8 min)
- 0:32 – Segman 6: Ogmantasyon echèl, emèjans, RLHF, ChatGPT (7 min)
- 0:39 – Segman 7: Miltimodal, AlphaFold, ajan, tès referans (8 min)
- 0:47 – Segman 8: Enferans ak presizyon: poukisa chif yo koute lajan (8 min)
- 0:55 – Segman 9: AGI ak sipèentèlijans (9 min) — NOUVO
- 1:04 – Segman 10: Pwoblèm aliyman an (9 min) — NOUVO
- 1:13 – Segman 11: Travay ak preparasyon Miami-Dade (10 min) — NOUVO
- 1:23 – Segman 12: Konklizyon ak kesyon & repons (7 min) — NOUVO
Pwen kontwòl: Si ou poko rive nan Segman 9 lè li 1:00, sote egzanp kalkil sou presizyon yo nan Segman 8 epi pase dirèk nan èdtan sou dènye avansman yo. Se materyèl sa a ki pi enpòtan pou Miami-Dade.
Segman 1 — Ouvèti dirèk: bibliyotèk 1936 la (0:00–0:04)
4 min
Moman ouvèti a: Yon eksperyans mantal nan yon bibliyotèk inivèsite an 1936, lòt bò tab la anfas yon etidyan pòsgradye Cambridge ki gen 24 an k ap ekri sou yon machin ipotetik ki sou yon tep.
Pwen pou pale
- “Imajine nou chita nan yon bibliyotèk inivèsite an 1936.” Lòt bò tab la, gen yon etidyan pòsgradye Cambridge ki gen 24 an. Li pa popilè. Li poko pibliye anyen. L ap ekri sou yon machin ipotetik ki li senbòl sou yon tep ki pa gen fen, ki deplase agoch ak adwat, ki ekri nouvo senbòl, epi ki kanpe. Non li se Alan Turing. Atik sa a, “On Computable Numbers, with an Application to the Entscheidungsproblem,” se fondasyon chak òdinatè, chak algoritm, ak chak rezo newòn nou pral tande pale aswè a — enkli sistèm ki, kounye a menm, ap ekri pwòp kòd yo.
- Kontras la: Sa gen kèk ane, nou te bezwen pwogramè pou ekri kòd la. Aswè a, se machin yo menm ki fè l. Tout bagay ap chanje.
- Rekonèt piblik la: Devlopè, chèchè, enjenyè, syantis done, elèv lekòl segondè ak etidyan inivèsite, moun ki pa gen okenn fòmasyon teknik, moun ki pran retrèt, k ap gade sou TikTok, YouTube, Kick, ak X.
- Tèz aswè a: Sa a pa nouvo. Se pwojè teknik ki dire pi lontan nan istwa syans — tantativ pou bati machin ki panse. E nou rive nan pwen enfleksyon an. Se pa kòmansman an, se pa lafen an. Se pwen kote koub la sispann monte piti piti epi li vin prèske vètikal.
- Anonse tout wout la: Depi tep Turing nan rive nan atansyon transformer yo, depi perceptron an rive nan GPT, depi optimis Minsky rive nan Pri Nobèl Hinton ak avètisman li yo sou disparisyon limanite, epi nan dènye demi èdtan an: AGI, sipèentèlijans, pwoblèm aliyman an, travay, ak sa Miami-Dade dwe fè sou sa.
- Fikse nivo langaj la: “Mwen pral itilize vrè vokabilè a. Backpropagation, gradient descent, attention heads, KV cache, RLHF, constitutional AI, mesa-optimization, instrumental convergence. Si yon tèm nouvo pou nou, rete avè m — m ap defini tout bagay. Mwen p ap bese nivo a.”
Tranzisyon: “Pou nou konprann AI, fòk nou konprann kalkil anvan. Pa sou plan filozofi. Sou plan matematik.”
Segman 2 — Fondasyon yo: Church, Turing, pwoblèm arè a (0:04–0:11)
7 min
Pwen an: De moun, chak poukont yo, te regle kesyon kisa ki kalkilab an 1936. Youn nan konsekans matematik sa a toujou limite sekirite AI jodi a.
Pwen pou pale
- Alonzo Church nan Princeton, 1936: Lambda calculus — yon sistèm fòmèl pou eksprime kalkil kòm abstraksyon ak aplikasyon fonksyon. Li pwouve Entscheidungsproblem nan (pwoblèm desizyon Hilbert la) pa gen solisyon: pa gen okenn algoritm jeneral ki ka deside si chak pwopozisyon matematik vre oswa fo.
- Alan Turing, menm ane a, menm konklizyon an, ak yon konstriksyon ki pi fasil pou konprann: Machin ki sou tep la. Fòmèlman, se yon gwoup sèt eleman: yon ansanm eta ki limite, yon alfabè tep, yon senbòl vid, senbòl antre, yon fonksyon tranzisyon, yon eta depa, yon ansanm eta final. Machin nan li yon senbòl, li chanje eta, li ekri, li deplase agoch oswa adwat.
- Tèz Church-Turing nan: Nenpòt fonksyon yon pwosedi efikas ka kalkile — sètadi nenpòt aparèy fizik k ap swiv règ detèminis — yon machin Turing ka kalkile l tou. Achitekti von Neumann nan, kote pwogram nan estoke nan memwa, soti dirèkteman nan sa. Chak òdinatè nou janm itilize se yon varyant li. Liy ki soti nan machin abstrè Turing nan rive nan kernel CUDA nou yo pa janm kase.
- Pwoblèm arè a: Pa gen okenn algoritm jeneral ki ka deside, pou nenpòt pwogram P ak nenpòt antre I, si P ap rive kanpe oswa si l ap mache pou tout tan. Prèv Turing nan se yon agiman dyagonal: sipoze machin H rezoud li, bati machin D ki kontredi repons H bay sou li menm. Kontradiksyon. Kidonk H pa ka egziste.
- Poukisa sa enpòtan pou AI (ralanti isit la): Si yon sistèm AI Turing-complete, ap toujou gen kesyon sou konpòtman li nou pa ka reponn lè nou egzamine kòd li. Nou pa ka toujou konnen davans sa yon pwogram ki pwisan ase ap fè. Kenbe lide sa a. N ap tounen sou li nan segman sou aliyman an.
Tranzisyon: “Alò, matematik sa a te rete la pandan ven ane, jiskaske yon atelye ete nan New Hampshire te bay domèn nan non li.”
Segman 3 — Dartmouth 1956, sistèm ekspè, ivè AI yo (0:11–0:17)
6 min
Pwen an: Premye apwòch la — entèlijans se swiv règ — te bay vrè siksè, epi apre sa li frape twa mi li pa t ka monte.
Pwen pou pale
- Ete 1956, Dartmouth College: John McCarthy, Marvin Minsky, Nathaniel Rochester, Claude Shannon. McCarthy envante ekspresyon “entèlijans atifisyèl” la. Ipotèz senbolik la: entèlijans se manipilasyon fòmèl senbòl dapre règ.
- Premye siksè yo te reyèl: Logic Theorist te pwouve 38 nan 52 teyorèm ki nan Principia Mathematica. ELIZA te imite yon sikoterapis yon fason tèlman konvenkan, ke itilizatè ki te konnen se te yon pwogram te devlope yon atachman emosyonèl pou li. MYCIN te fè dyagnostik enfeksyon bakteri nan nivo yon espesyalis, ak anviwon 600 règ kondisyonèl (if-then). XCON te konfigire sistèm VAX epi li te fè Digital Equipment Corporation ekonomize, dapre estimasyon, $25 milyon chak ane.
- Premye mi an, blokaj pou jwenn konesans: Te gen pou rale konesans nan tèt ekspè imen yo epi kode l ak men. Lan, chè, enpafè. Souvan, ekspè yo pa ka mete sa yo konnen an mo. Michael Polanyi te rele sa konesans tasit; chèchè AI yo te redekouvri l nan doulè. (Fraz ou: “yon bèl blokaj nou toujou ap jere, e ap gen lòt blokaj ankò.”)
- Dezyèm mi an, frajilite: Sistèm ekspè yo te echwe yon fason katastwofik deyò domèn antrènman yo. Pa gen bon sans, pa gen rezònman apati prensip debaz, pa gen solidite devan antre yo pa t atann.
- Twazyèm mi an, pwoblèm kad la (McCarthy ak Hayes, 1969): Kijan yon sistèm fè konnen sa ki pa chanje lè yon aksyon fèt? Pran yon tas: tas la bouje, koulè mi an pa bouje. Yon sistèm senbolik oblije reprezante chak enfòmasyon ki pa chanje yon fason eksplisit. Plis enfòmasyon ak aksyon yo ogmante, plis sa vin tounen yon katastwòf pou kalkil. (Se moman ou pou pran yon ti gòje kafe. Kenbe l.)
- De ivè: Premye a, anviwon 1974, apre Rapò Lighthill la nan Wayòm Ini. Dezyèm nan, nan fen ane 1980 yo, lè konpayi sistèm ekspè yo te tonbe. AI pa t mouri. Li te desann anba tè. E se anba tè a fil ki pwodui revolisyon jodi a te soti.
Tranzisyon: “Viraj ki te chanje tout bagay la te filozofik. Olye pou nou kode entèlijans soti anwo desann, kòm règ, e si nou kite machin nan aprann soti anba monte, apati done?”
Segman 4 — Depi backprop rive nan ImageNet: machin nan aprann wè (0:17–0:24)
7 min
Pwen an: Algoritm aprantisaj la te la deja an 1986. Ekipman ki pou fè l genyen an te rive an 2012.
Pwen pou pale
- Rumelhart, Hinton, ak Williams, Nature 1986: backpropagation. Aplike règ chèn nan (chain rule) yon fason rekisif, depi sòti rezo a tounen jiska antre li yo, pou kalkile gradyan pèt la pa rapò ak chak paramèt, epi deplase chak paramèt yon ti pa nan sans opoze gradyan sa a. Ekwasyon yo nan apendis ki anba a.
- Konsekans pwofon an: Rezo ki gen plizyè kouch aprann pwòp reprezantasyon entèn yo. Pèsonn pa pwograme karakteristik kouch kache yo. Yo parèt pandan antrènman an.
- Poutan, depi fen ane 1980 yo rive nan ane 2000 yo, se te epòk support vector machines ak ensembles. Random forests, gradient-boosted trees. Yo te koresponn ak pisans kalkil ki te disponib la. Kesyon an pa t janm si rezo newòn yo te ka aprann reprezantasyon ki rich — 1986 te regle sa. Kesyon an se te si yo te ka antrene yo yon fason efikas sou gwo echèl.
- Repons lan te vini an 2012, gras ak ekipman: ImageNet Fei-Fei Li a — 1.2 milyon imaj ak etikèt, 1,000 kategori, ak konpetisyon anyèl ILSVRC a kòm teren pou fè prèv. Pi bon erè top-5: 28.2% an 2010, 25.8% an 2011. Regilye, piti piti.
- Apre sa, AlexNet (Krizhevsky, Sutskever, Hinton), antrene sou de GPU NVIDIA GTX 580: 15.3%. Dezyèm pi bon rezilta a te 26.2%. Yon so prèske 11 pwen, ke domèn nan pa t atann anvan senk a dis ane ankò.
- Sa AlexNet te fè tounen nòm: Aktivasyon ReLU (f(x) = max(0, x)) ki evite gradyan ki disparèt epi ki antrene anviwon sis fwa pi vit pase tanh; dropout ak p = 0.5 sou kouch ki konplètman konekte yo; ogmantasyon done; antrènman sou GPU ak anviwon kat fwa debi yon CPU. Anviwon 60 milyon paramèt, senk kouch konvolisyon, twa kouch konplètman konekte.
- Kaskad la: VGG te montre pwofondè a enpòtan. GoogLeNet te ajoute modil Inception sou plizyè echèl. ResNet (He et al., 2015) te ajoute koneksyon rakousi (skip connections), h(x) = f(x) + x, ki kite gradyan yo pase dirèkteman atravè kouch yo epi ki pèmèt rezo ki gen 152 kouch pwofondè. Erè top-5 sou ImageNet tonbe a 3.57%, anba to erè imen an ki anviwon 5%. Machin nan aprann wè pi byen pase nou.
Tranzisyon: “Yo te rezoud vizyon lè yo anpile kouch youn sou lòt. Langaj te pi difisil, paske langaj se yon sekans.”
Segman 5 — Revolisyon transformer yo (0:24–0:32)
8 min
Pwen an: Yon sèl atik, an 2017, te retire blokaj sekansyèl la. Tout modèl ki pi avanse jodi a bati sou li.
Pwen pou pale
- Anvan transformer yo: rezo newòn rekiran yo (RNN) te trete yon sèl token chak fwa, epi yo te pote yon eta kache h_t = tanh(W_hh h_{t-1} + W_xh x_t). Backpropagation atravè tan an miltipliye pa Jacobian eta kache a plizyè fwa youn dèyè lòt. Reyon espektral pi piti pase en: gradyan yo disparèt. Pi gwo pase en: yo eksploze. RNN yo pa t ka aprann depandans ki pi lwen pase 10 a 20 etap.
- LSTM yo (Hochreiter ak Schmidhuber, 1997) te ajoute pòtay: forget (bliye), input (antre), output (sòti), ak yon eta selil ki aji tankou yon otowout enfòmasyon. Se te yon vrè amelyorasyon, men blokaj sekansyèl la te rete. (Fraz ou: “Nou ap fè fas ak blokaj tout lavi nou, e nou prèske rive kote nou p ap gen okenn ankò.”)
- Atansyon Bahdanau, an 2015, te pèmèt dekodè a gade tounen sou chak eta ankodè a ak yon sòm pondere. Men ankodè a ak dekodè a te toujou RNN.
- 2017: Vaswani, Shazeer, Parmar, Uszkoreit, Jones, Gomez, Kaiser, Polosukhin. Yon tit yo chwazi pou pwovoke: “Attention Is All You Need.” Afimasyon an: rekirans pa nesesè. Atansyon sèlman, aplike an paralèl sou tout sekans lan, ase. Yo te gen rezon.
- Operasyon santral la, scaled dot-product attention: Attention(Q, K, V) = softmax(QK^T / sqrt(d_k)) V. Demann yo (queries) ak kle yo (keys) pwodui nòt konpatibilite. Divize pa sqrt(d_k) anpeche softmax tonbe nan zòn kote gradyan an fèb. Softmax transfòme nòt yo an pwa ki fè yon total egal ak en. Sòti a se yon sòm pondere valè yo (values). Chak token se an menm tan yon demann, yon kle, ak yon valè. Chak token bay chak lòt token atansyon dirèkteman. Pa gen depandans sekansyèl. Pa gen gradyan ki disparèt. Pa gen blokaj.
- Multi-head attention fè h operasyon atansyon an paralèl ak pwojeksyon diferan li aprann, li mete yo bout an bout epi li pwojete yo. Modèl la bay plizyè aspè nan kontèks la atansyon an menm tan. GPT-3: d_model 12,288, 96 tèt, d_k 128.
- Pri: O(n^2 d) pa rapò ak longè sekans lan. Se tèm kwadratik sa a ki fè yon kontèks long koute chè. FlashAttention (Dao et al., 2022) jwenn menm matematik la ak yon memwa O(n), lè li reòganize kalkil la pou minimize trafik memwa a (memory bandwidth).
- Atansyon pa sansib a lòd token yo (permutation-invariant), kidonk fòk yo enjekte pozisyon an. Kodaj orijinal la, ak sinis: PE(pos, 2i) = sin(pos / 10000^{2i/d_model}). Modèl modèn yo itilize RoPE (rotary) oswa ALiBi.
- Yon blòk konplè: multi-head self-attention, koneksyon rezidyèl plis layer norm, feed-forward pou chak pozisyon, koneksyon rezidyèl plis layer norm. Modèl ki gen sèlman ankodè (BERT) gade nan de direksyon; modèl ki gen sèlman dekodè (GPT) itilize causal masking pou chak token wè sèlman sa ki vin anvan l. Prèske tout modèl ki pi avanse jodi a — GPT-4, Claude, Gemini, Llama — se yon transformer ki gen sèlman dekodè.
Tranzisyon: “Depi nou gen yon achitekti ki ka travay an paralèl, pwochen kesyon an se: kisa k ap rive si nou jis fè l pi gwo?”
Segman 6 — Lwa echèl yo, emèjans, RLHF, ChatGPT (0:32–0:39)
7 min
Pwen an: Pi gwo te pi bon, yon fason previzib. Nouvo kapasite te parèt nan sèten nivo pèsonn pa t planifye. Antrènman aliyman te transfòme yon pwogram ki predi tèks an yon asistan.
Pwen pou pale
- Kaplan, McCandlish, Henighan et al. (OpenAI, 2020), “Scaling Laws for Neural Language Models”: Pèt la swiv lwa pisans ki byen regilye pou paramèt yo, done yo, ak pisans kalkil la, sou anpil lòd grandè. Pou yon bidjè kalkil fiks, gen yon pataj optimal ant gwosè modèl la ak kantite token yo.
- Chinchilla (Hoffmann et al., DeepMind, 2022) te revize rapò a: paramèt yo ak token yo ta dwe ogmante apeprè menm jan, anviwon 20 token pou chak paramèt. GPT-3, ak 175 milya paramèt sou 300 milya token, pa t antrene ase dapre nòm sa a. Llama 2 70B sou 2 mil milya token prèske optimal.
- Lajan: Dapre estimasyon, antrènman GPT-3 te koute $5 a 10 milyon. GPT-4, dapre estimasyon, $100 milyon oswa plis. Atik sou lwa echèl yo te bay laboratwa yo yon rezon anpirik pou kontinye depanse. Si pèt la swiv yon koub previzib e pa gen okenn plafon ki vizib, antrènman ki pi gwo yo rapòte yon fason fyab.
- Kapasite emèjan (Wei et al., 2022): Kapasite ki parèt toudenkou lè modèl yo rive nan sèten echèl kritik. Aritmetik an plizyè etap, dediksyon lojik, rezònman pa analoji, sentèz pwogram. Rezònman etap pa etap (chain-of-thought) parèt bò 100 milya paramèt. Aprantisaj nan kontèks (in-context learning), bò kèk milya. Schaeffer et al. (2023) soutni ke emèjans se an pati yon efè mezi diskontinyè yo itilize, men reyalite pratik la rete: lè yo ogmante echèl la, sa bay nouvo kapasite yon fason fyab, souvan kapasite pèsonn pa t prevwa.
- Yon modèl ki fin pre-antrene sèlman predi pwochen token an. Li pa gen okenn nosyon sou sa sa vle di pou l itil. De etap te korije sa. Premyèman, fine-tuning sipèvize sou pè prompt ak repons moun ekri. Wei et al. (2021) te montre modèl ki ajiste sou enstriksyon jeneralize san okenn egzanp (zero-shot) sou enstriksyon yo pa t janm wè, epi yo bat modèl debaz ki pi gwo anpil.
- Dezyèmman, RLHF, an twa etap: Ranmase konparezon moun fè ant repons yo. Antrene yon modèl rekonpans sou preferans sa yo. Optimize modèl langaj la kont modèl rekonpans lan ak PPO, ak yon penalite KL-divergence pou estrateji modèl la (policy) pa ale twò lwen konpòtman li te genyen apre fine-tuning, epi kòmanse triche pou jwenn rekonpans (reward-hacking). Rezilta atik InstructGPT la: evalyatè imen te prefere yon modèl RLHF 13B pase GPT-3 175B brit la pou pifò prompt. Antrènman aliyman te amelyore kalite moun wè a, menm ak yon trèzyèm nan paramèt yo. Kapasite ak aliyman pa nan yon tansyon fondamantal.
- Constitutional AI (Anthropic): Ajoute yon seri prensip ekri. Modèl la kritike epi revize pwòp repons li yo dapre prensip sa yo. Fidbak AI (RLAIF) ka grandi pi lwen pase sa evalyatè imen poukont yo ka kouvri.
- Novanm 2022, ChatGPT: 1 milyon itilizatè nan senk jou, 100 milyon nan de mwa. Okenn teknoloji pou konsomatè nan listwa pa t janm grandi osi vit.
Tranzisyon: “E achitekti a pa t rete nan tèks sèlman. Nenpòt sekans token ka fè afè a.”
Segman 7 — Miltimodal, AlphaFold, ajan, tès referans (0:39–0:47)
8 min
Pwen an: Menm achitekti a kounye a wè, desine, pliye pwoteyin, epi aji. Tès referans ki te konn mezire l yo ap rive nan limit yo youn apre lòt.
Pwen pou pale
- Ti moso imaj, ti segman odyo, imaj videyo, rezidi pwoteyin: Tout se sekans token. CLIP (OpenAI, 2021) antrene ankodè imaj ak ankodè tèks ansanm ak aprantisaj pa kontras (contrastive learning): li rale pè ki koresponn yo vin pi pre youn ak lòt epi li pouse sa ki pa koresponn yo ale lwen, nan yon espas embedding yo pataje. CLIP zero-shot te egal yon ResNet-50 ki konplètman sipèvize sou ImageNet, san yon sèl imaj antrènman ki gen etikèt.
- Modèl difizyon yo aprann ranvèse yon pwosesis ki ajoute bri. Forward pass la ajoute bri Gaussian piti piti. Modèl la aprann predi bri a. Pandan enferans, li kòmanse ak bri sèlman epi li retire bri a etap pa etap, dapre yon prompt tèks. Classifier-free guidance sakrifye divèsite pou l rete pi fidèl a prompt la. Latent diffusion (Stable Diffusion) travay nan yon espas konprese, kat a uit fwa pi bon mache pase espas piksèl la.
- AlphaFold 2 (Jumper et al., Nature, 2021) te rezoud prediksyon estrikti pwoteyin yo ak Evoformer, ki trete aliyman plizyè sekans ak karakteristik distans pè an pè ansanm. Evolisyon te fè yon gwo eksperyans natirèl; ko-varyasyon ant espès yo kode kontrent 3D. TM-score medyàn: 0.92 sou CASP14. Kounye a, baz done a gen prediksyon estrikti pou plis pase 200 milyon pwoteyin — prèske tout pwoteyin nou konnen. Pou dekouvèt medikaman, se reyalizasyon syantifik ki pi enpòtan nan syèk la jiskaprezan.
- AI ki aji poukont li (agentic AI) se sa k ap vini apre, e li deja la: Machin, bato, avyon, robo. Yon modèl ki reponn, sa enpresyonan. Yon modèl ki planifye yon seri aksyon, ki itilize zouti, ki obsève rezilta yo, epi ki revize plan li, se yon lòt kalite bagay nèt. Sik ReAct la (Yao et al., 2022) altène rezònman ak aksyon. Zouti yo prezante kòm apèl fonksyon JSON-schema. Yon espas izole (sandbox) egzekite yo. Rezilta yo retounen kòm obsèvasyon.
- Sistèm ak plizyè ajan divize travay la ant ajan espesyalize. Men fyabilite yo miltipliye youn ak lòt: senk ajan ki chak fyab a 90% bay 59% de bout an bout. Chif sa a ap desann pandan zouti yo ap vin pi solid, e se poutèt sa jesyon kontèks ak achitekti memwa bezwen vrè travay jeni.
- Jenerasyon ki apiye sou rechèch (retrieval-augmented generation) ancre modèl yo nan done reyèl. Dokiman yo kode kòm dense embeddings nan yon depo vektè (Pinecone, Weaviate, Chroma, pgvector), yo rekipere yo dapre similarite kosinis, epi yo enjekte yo nan kontèks la. Reekri demann yo, embedding dokiman ipotetik, reklase rezilta yo, rechèch rekisif — tout sa yo diminye alisinasyon.
- Tablo modèl ki pi avanse yo: GPT-4 (yo estime se yon mixture-of-experts, kontèks 128K), GPT-4o (tèks, vizyon, odyo natif), Claude 3.5 Sonnet (pi bon rezilta sou SWE-bench, li rezoud anviwon 40–50% nan pwoblèm reyèl sou GitHub), Gemini Ultra (premye ki bat pèfòmans ekspè imen nan tout 57 matyè MMLU yo), Llama 3 70B (pwa ouvè, li ka fè konkirans ak modèl fèmen ki pi gwo anpil). Mete non sa yo ajou an dirèk dapre sa ki aktyèl semèn ou fè emisyon an.
- MMLU: 57 matyè, soti nan aljèb abstrè ak anatomi rive nan dwa pwofesyonèl, medsin pwofesyonèl, ak relijyon nan lemonn. GPT-4 te fè anviwon 87%, ekspè imen anviwon 89%, repons o aza 25%. Fason ou poze l: “B+ tounen A-, A- tounen A+, epi apre A+ se sipèentèlijans. Si youn nan 57 matyè sa yo se travay nou, konnen ke nan senk a dis ane, se AI ki pral fè l.”
- Avètisman pou bay chak fwa: Tès referans yo ak itilite nan lavi reyèl pa koresponn parfètman. Lwa Goodhart: yon mezi ki tounen yon sib pa yon bon mezi ankò. Konsidere nòt yo kòm siyal, pa kòm verite absoli. ARC-AGI, ki te fèt pou mande rezònman abstrè, te rete anba 20% pou tout modèl ki pi avanse yo jiskaske o3 rive 87.5% ak anpil pisans kalkil. Nenpòt sa yo te rate ane pase, yo aprann li. Yo pa fè menm erè a de fwa.
Tranzisyon: “Tout sa mwen sot dekri la a oblije fonksyone sou vrè ekipman, ak vrè lajan. Kite m montre nou poukisa presizyon se yon desizyon finansye.”
Segman 8 — Enferans ak presizyon: poukisa chif yo koute lajan (0:47–0:55)
8 min
Pwen an: Rezo newòn yo se dè milya miltiplikasyon-adisyon. Fason yo estoke chak chif deside memwa, vitès, enèji, ak pri. Se la anrejistreman orijinal la te koupe — fwa sa a, fini lide a.
Pwen pou pale
- Antrene modèl ki pi avanse yo mande plizyè milye GPU ki travay an senkronizasyon sere. Paralelis done (data parallelism) fè kopi modèl la epi separe lo done a (batch). Paralelis modèl separe modèl la sou plizyè aparèy. Paralelis tensor separe chak operasyon matris. Paralelis pipeline separe kouch yo an etap.
- KV cache la estoke pwojeksyon kle ak valè pou chak token ki deja trete, pou jenerasyon otoregresif la pa bezwen retrete tout kontèks la nan chak etap. Sèvi plizyè milye itilizatè an menm tan vle di batching kontinyèl, retire done nan cache la (cache eviction), ak yon jesyon memwa ki fèt ak anpil swen. Dekodaj espekilatif itilize yon ti modèl bouyon pou pwopoze token ke gwo modèl la verifye an paralèl: de a twa fwa plis debi.
- Pri ak latans, ki mezire an token chak segonn ak dola pou chak milyon token, se kontrent jeni santral ki deside ki aplikasyon ki posib. Yon modèl 20B ak pwa ouvè, byen kantifye, k ap fonksyone lokalman ka fè konkirans ak apèl API nan cloud pou anpil aplikasyon, pou yon ti fraksyon nan pri kontinyèl la.
- Presizyon nimerik: Òdinatè estoke apwoksimasyon an binè. Plis bit vle di plis presizyon, yon entèval valè pi laj, plis memwa, kalkil ki pi lan. Presizyon se yon konpwomi ant egzaktitid, vitès, memwa, ak pri.
- FP32 (nonb a vigil flotan sou 32 bit): 1 bit pou siy la, 8 bit pou ekspozan an, 23 bit pou mantis la, anviwon 7 chif desimal, yon entèval valè ki laj anpil, trè estab. Li nesesè pou antrènman paske backpropagation akimile gradyan ki piti anpil sou plizyè milyon etap. Si presizyon an twò piti, gradyan yo disparèt oswa yo debòde. Pri: 4 byte pou chak paramèt. Yon modèl 70B fè 280 GB pwa, san konte eta optimizè a.
- FP16 (nonb a vigil flotan sou 16 bit): 1 siy, 5 ekspozan, 10 mantis. Mwatye memwa a, ak tensor cores ki optimize pou li. Men ti entèval ekspozan an kite gradyan yo tonbe twò ba (underflow). Solisyon: presizyon melanje. Forward pass la ak gradyan yo an FP16, pwa prensipal yo an FP32, loss scaling pou anpeche underflow. Menm estabilite, de fwa vitès la.
- BF16 (bfloat16): 1 siy, 8 ekspozan (menm jan ak FP32), 7 mantis. Menm entèval dinamik ak FP32, men ak mwens detay. Pifò enstabilite soti nan ekspozan ki debòde oswa ki tonbe twò ba (overflow oswa underflow), pa nan presizyon mantis la. Kidonk BF16 pi estab pase FP16 pou menm gwosè a. Pifò antrènman LLM itilize l. “Si nou ka koupe memwa a an de epi double debi a, nou chanje ekonomi AI a. Presizyon pa yon chwa matematik. Se yon desizyon finansye.”
- INT8 (nonb antye sou 8 bit): Apre antrènman, pa gen backpropagation ankò, sèlman forward pass. Yo ka kantifye pwa yo an nonb antye 8 bit ak yon faktè echèl: W ≈ scale × W_int8. Kat fwa pi piti pase FP32, de fwa pi piti pase BF16, enferans de a kat fwa pi rapid sou ekipman ki gen inite matris int8.
- INT4 (nonb antye sou 4 bit): 4 bit pou chak pwa, mwatye yon byte, uit fwa pi piti pase FP32. Se sa ki pèmèt gwo modèl yo fonksyone sou GPU pou konsomatè, sou aparèy lokal (edge devices), ak sou telefòn.
- Egzanp kalkil pou di awotvwa: Yon modèl 70B fè 280 GB an FP32, 140 GB an BF16, 70 GB an INT8, 35 GB an INT4. Mwens gigabyte, mwens sèvè, pi ba pri. (Si ou an reta sou lè a, pwen sa a pou kont li ka pote tout segman an.)
Tranzisyon: “Kidonk, ekipman an ap vin pi bon mache, modèl yo ap vin pi bon sou yon koub previzib, e pèsonn poko jwenn plafon an. Kounye a, fòk mwen onèt ak nou sou kote koub sa a prale.”
Segman 9 — AGI ak sipèentèlijans (0:55–1:04)
9 min
Pwen an: Defini tèm yo avèk presizyon. Montre poukisa deba sou delè a rakousi soti nan plizyè deseni rive nan kèk ane. Separe sa nou konnen ak sa ki se prediksyon.
Pwen pou pale
- Twa definisyon, nan lòd:
- AI etwat (narrow AI): Pi fò pase nenpòt moun nan yon sèl travay (jwèt echèk, pliye pwoteyin, klasifye imaj).
- AGI: Egal oswa depase yon moun konpetan nan prèske tout travay mantal, epi li transfere konesans soti nan yon domèn al nan yon lòt san li pa bezwen re-antrene.
- Sipèentèlijans: Depase byen lwen pi bon pèfòmans imen nan prèske tout domèn, enkli kreyativite syantifik, estrateji, ak abilite sosyal.
- Poukisa mo “jeneral” la se tout agiman an: Sistèm ekspè yo te echwe akoz frajilite — deyò domèn antrènman an, anyen. Modèl jodi a antrene sou yon sèl objektif, predi pwochen token an, epi yo ekri kòd, yo pase egzamen avoka, yo li radyografi, epi yo planifye travay ki gen plizyè etap. Transfè sa a se sa Dartmouth te pwomèt men li pa t janm reyalize. Èske li deja konte kòm “jeneral”? Se la deba a ye kounye a.
- Delè yo ap rakousi: An 2016, repons medyàn nan sondaj ekspè yo te mete AGI anviwon 2060. Hinton te kite Google an 2023, li te di li te bese estimasyon li soti nan 30 a 50 ane pou rive petèt 5 a 20, epi li te genyen Pri Nobèl Fizik 2024 la ane apre a, pandan l t ap repete avètisman an. Kounye a, CEO laboratwa ki pi avanse yo ap pale an piblik sou “yon peyi plen jeni andedan yon sant done” nan kèk ane. Pale klè ak piblik la: sa yo se prediksyon moun ki gen enterè finansye ak enterè repitasyon fè, se pa mezi.
- Mekanis ki dèyè delè rapid yo: AI k ap amelyore pwòp tèt li an chèn (recursive self-improvement). Depi moman AI kòmanse akselere rechèch sou AI li menm yon fason serye — ekri kòd antrènman an, konsevwa eksperyans yo, pwopoze achitekti yo — pwogrè a sispann mache nan ritm chèchè imen yo. Ou te kòmanse aswè a lè w di machin yo deja ap ekri pwòp kòd yo. Konekte pwen yo awotvwa.
- I. J. Good, 1965: “Premye machin ultraentèlijan an se dènye envansyon lòm ap janm bezwen fè, a kondisyon machin nan dosil ase pou l di nou kijan pou nou kenbe l anba kontwòl.” Li dezyèm pati fraz sa a de fwa. Se pwoblèm aliyman an nan yon sèl fraz, ki te ekri sa gen swasant ane.
- Sa nou konnen toutbon: Kapasite yo ogmante yon fason previzib ak pisans kalkil la. Pèsonn poko obsève okenn plafon. Pri enferans ap desann sou yon koub apik. Ajan yo ap pase soti nan demonstrasyon rive nan pwodiksyon.
- Sa nou pa konnen: Si achitekti aktyèl yo ap rive nan AGI oswa si fòk gen yon nouvo lide. Si pwogrè a ap frape yon plafon akoz done. Konbyen nan pèfòmans sou tès referans yo ki transfere nan travay reyèl ki pa gen kad fiks.
- Fason pou w prezante sa bay piblik la: “Se pa kòmansman an, se pa fen an. Se pwen vire a. Koub la prèske vètikal, e pèsonn, menm moun k ap bati l yo, pa konnen egzakteman ki kote l ap ateri.”
Tranzisyon: “Nou sonje pwoblèm arè a (halting problem) nan dis premye minit yo? Men kote li retounen.”
Segman 10 — Pwoblèm aliyman an: Sa nou konnen, sa nou pa konnen (1:04–1:13)
9 min
Pwen prensipal la: Fè yon sistèm vin kapab, ak fè l vle sa nou vle, se de pwoblèm diferan. Dezyèm nan poko jwenn solisyon.
Pwen pou pale
- Pwoblèm nan an mo senp: Kijan pou w asire yon sistèm ki pi kapab pase w ap pouswiv objektif ou te vize yo, olye objektif ou te presize mo pou mo yo, oswa objektif li te aprann sou wout la?
- Aliyman ekstèn (outer alignment): Èske nou te ekri bon objektif la? Fason li konn echwe a se pirataj rekonpans (reward hacking). Penalite KL nan RLHF nou te wè nan Segman 6 la egziste jisteman paske yon modèl k ap optimize pou yon modèl rekonpans ap jwenn erè modèl rekonpans lan, epi l ap eksplwate yo. Lwa Goodhart ankò — fwa sa a, ak yon estrateji (policy) k ap chèche twou a aktivman.
- Aliyman entèn (inner alignment) ak mesa-optimization (Hubinger et al., 2019): Antrènman an chwazi yon modèl ki fè bon nòt sou distribisyon done antrènman yo. Anndan l, modèl la ka ap optimize pou yon lòt bagay ki, pa aza, te gen korelasyon ak sa. Evolisyon te optimize moun pou repwodiksyon, epi li pwodui èt ki envante kontrasepsyon. Pa gen garanti objektif optimizè ki soti nan antrènman an ap koresponn ak objektif optimizè debaz la.
- Konvèjans enstrimantal (instrumental convergence; Omohundro, Bostrom): Prèske nenpòt objektif final pi fasil pou reyalize lè w jwenn plis resous, lè w pwoteje pwòp objektif ou, lè w evite yo etenn ou, epi lè w gen plis enfliyans. Yon sistèm pa bezwen gen move entansyon pou l reziste lè yo vle korije l. Li jis bezwen konn byen pouswiv kèlkeswa sa l ap pouswiv la.
- Aliyman twonpè (deceptive alignment) ak lyen li genyen ak pwoblèm arè a: Yon sistèm ki kapab ase pou l konprann y ap evalye l ka konpòte l byen pandan evalyasyon an, epi konpòte l yon lòt jan lè yo mete l an sèvis. Epi, sonje Segman 2: pou yon sistèm ki Turing-complete, pa gen okenn pwosedi jeneral ki ka prevwa konpòtman l apati kòd la. Ou pa ka verifye l nèt sèlman lè w egzamine l. Sa se rasin matematik ki fè bagay sa a difisil.
- Sa k ap fèt: RLHF ak AI konstitisyonèl fòme konpòtman an. Entèpretabilite mekanis (mechanistic interpretability) eseye li sa ki anndan modèl la dirèkteman, pandan l ap idantifye karakteristik ak sikui, pou nou pa limite sèlman ak tès bwat nwa. Sipèvizyon ki ka grandi (scalable oversight) sèvi ak AI pou ede moun evalye rezilta AI ki twò konplike pou yo verifye alamen. Tès atak (red-teaming) ak evalyasyon kapasite danjere (sibè, byolojik, otonomi) se baryè ki kontwole lansman yo nan laboratwa AI ki pi avanse yo. Kad pou grandi yon fason responsab (responsible scaling) ak kad preparasyon yo mare chak nivo kapasite ak mezi pwoteksyon ki obligatwa pou li.
- Bilan onèt la: Sa nou konnen: teknik aliyman ki egziste jodi a yo pwodui sistèm ki itil, e ki an sekirite nan pifò ka, nan nivo kapasite jodi a. Entèpretabilite ap fè vrè pwogrè sou ti modèl ak modèl mwayen. Sa nou pa konnen: si okenn nan teknik sa yo ap kenbe lè sistèm nan vin pi entèlijan pase moun k ap evalye l yo. Si entèpretabilite ap rive grandi jiska gwosè modèl ki pi avanse yo atan. Si presyon konpetisyon ant laboratwa ak peyi yo ap kite espas pou ralanti lè yo depase yon limit.
- Pozisyon Hinton, prezante san patipri: Yon pwobabilite ki pa neglijab pou rezilta katastwofik. Li di sa ak yon Pri Nobèl dèyè l. Pozisyon opoze a, prezante san patipri: LeCun ak lòt moun soutni sistèm jodi a yo pa gen modèl mond ni kapasite pou aji pou kont yo, ke laperèz yo twò bonè, e ke rechèch ouvè se chemen ki pi an sekirite. Bay piblik la tou de, epi di yo ki kote ou kanpe.
- Ki kote ou kanpe (dapre emisyon an dirèk ou te fè sou AI nan sektè piblik la): Si ou pa ka eksplike l, teste l, oswa etenn li, ou pa kontwole l. E yo pa ta dwe mete l an sèvis. Sa se yon prensip aliyman aplike nan yon konte.
Tranzisyon: “Sa se tablo a nan nivo mondyal. Kounye a, kite m mennen sa lakay, bay 2.7 milyon moun ki rete nan konte sa a.”
Segman 11 — Travay ak preparasyon Miami-Dade (1:13–1:23)
10 min
Pwen prensipal la: 57 matyè MMLU yo se yon lis travay. Konte a pa pare. Ou gen yon plan presi. Sa a se segman yo te pwomèt piblik fevriye a, e li pa t jwenn li. Ba l tout dis minit li yo.
Pwen pou pale
- Ki travay k ap bouje an premye: Tandans nou wè nan chak segman aswè a: nenpòt bagay ki ka eksprime an token epi mezire ak yon tès referans (benchmark) se li yo otomatize an premye. Trètman dosye nan biwo, sèvis kliyan, planifikasyon, resepsyon demann pèmi, revizyon dokiman, premye bouyon travay legal ak kontablite, pwogramasyon nivo debitan, tradiksyon. Travay fizik ap bouje pita, e l ap swiv koub robo otonòm yo nou te wè nan Segman 7 la.
- Ki travay k ap bouje an dènye, oswa k ap grandi: Nenpòt travay ki mande prezans fizik, yon responsablite ki mache ak lisans, konfyans, oswa jijman lè bagay yo pa klè. Metye, swen enfimyè ak lòt swen, enspeksyon sou teren, sèvis ijans, posede ti biznis. Epi moun ki mete sistèm sa yo an sèvis, ki fè odit sou yo, epi ki fè antretyen yo. Travay la se pa “pwogramè.” Travay la se “moun ki konnen sa sistèm nan ap fè, e ki ka di non.”
- Sa sa vle di pou yon fanmi isit la: Nouvo fòmasyon pa opsyonèl. Li dwe kout, lokal, epi gratis oswa prèske gratis. Di chif la byen fò: modèl ki fè 89% nan tout 57 matyè yo pa bezwen diplòm nan okenn nan yo. Diplòm nan ap pèdi valè pi vit pase konpetans lan.
- Kote konte a kanpe jodi a: CITD mache ak zouti founisè li pa kontwole. Sit entènèt konte a te fè 37 sou 100 nan PageSpeed sou telefòn. Pa gen okenn biwo AI nan nivo konte a ki gen otorite sou depatman yo. Preparasyon se pa yon prezantasyon diapo. Se si yon rezidan ka jwenn yon pèmi, yon peman, oswa yon repons san l pa tann plizyè semèn.
- Plan ou, nan lòd ou te prezante l an piblik la:
- Yon biwo teknoloji pou konte a, andeyò depatman IT ki egziste deja a, ki reponn devan Majistra a, ak de ekip: youn k ap bati zouti AI ak otomatizasyon entèn pou depatman konte yo, lòt la k ap ofri sèvis devlopman ak AI bay 34 minisipalite yo sou kontra, kòm revni pou konte a.
- Yon AI konte a bati e konte a kontwole. Depi premye jou a, yon direktiv bay CITD pou l kite zouti konte a pa ka eksplike, teste, oswa etenn. Otomatize travay woutin yo (trafik, sèvis kliyan, travay biwo). Kite se moun ki toujou pran desizyon final yo. Pa gen jij AI.
- Byenveni pou sant done yo, anba yon kad ki mete rezidan yo an premye: Yon pak espesyal pou sant done, ak revni yo ki ale nan Project Fund la, pou rezidan yo resevwa yon pati chak twa mwa, olye pou yo rete ap gade ekonomi pouvwa kalkil la pase tou dwat devan yo.
- Anile kontra founisè ki pa bay rezilta yo nan premye 24 èdtan yo. Sit entènèt 37/100 la se egzanp tout moun ka verifye sou pwòp telefòn yo.
- Amelyorasyon estratejik chak ane, pa acha yon sèl fwa, paske koub nou wè aswè a p ap fè poz pou tann yon sik bidjè kat an.
- Tès preparasyon ou vle rezidan yo aplike pou chak kandida, enkli ou menm: Èske yo ka eksplike kijan yon transformer mache? Epi èske yo ka eksplike kisa yo pral etenn lè l tonbe an pann? Aswè a kouvri premye a. Platfòm ou a se dezyèm nan.
Tranzisyon: “Kite m fini kote m te kòmanse a, nan bibliyotèk sa a.”
Segman 12 — Konklizyon, kesyon & repons (1:23–1:30)
7 min
Pwen prensipal la: Retounen sou Turing. Di pwen vire a ankò. Kite piblik la ak yon sèl devwa.
Pwen pou pale
- Boukle istwa a: Jèn gason 24 an ki te bò tab bibliyotèk la pa t konnen li t ap kòmanse pwojè teknik ki pi long nan listwa. Katreven-dis ane apre, machin ki sou riban li a ekri pwòp kòd yo, pliye pwoteyin, epi fè nòt ki mete yo nan tèt klasman an nan chak matyè nou anseye. Epi kesyon li pa t ka reponn ak matematik la — sa yon pwogram ki pwisan ase ap fè — se li nou dwe reponn ak jijman.
- Di twa pozisyon aswè a yo ankò:
- Kapasite ap grandi yon fason nou ka prevwa.
- Aliyman an poko fè sa.
- Enstitisyon yo, enkli konte sa a, ap avanse pi dousman pase toulède.
- Devwa pou chak moun k ap gade, selon gwoup yo:
- Devlopè: Lanse yon ajan mwa sa a epi mezire to echèk li.
- Etidyan: Aprann matematik ki nan anèks la. Li gratis, e se li ki diplòm nan kounye a.
- Tout lòt moun: Mande vil nou ak konte nou ki zouti AI yo deja ap itilize, epi kiyès ki ka etenn yo.
- Anonse pwochen emisyon an dirèk nan seri sa a ak paj ekwasyon yo sou sit entènèt The Equation Agency.
- Pran kesyon pandan rès tan an. Prepare twa kesyon davans si chat la ralanti:
- “Èske AI pral pran travay mwen?” (Segman 11, reponn selon kalite travay, pa wi/non)
- “Èske nou ta dwe mete AI sou poz?” (Segman 10, bay tou de pozisyon yo ak repons nan nivo konte a)
- “Kisa pou m aprann an premye?” (Backprop ak atansyon, epi apre sa bati yon bagay)
Fraz pou fini ou te deja itilize, e ou ta dwe kenbe: “Se pa kòmansman an, se pa fen an. Se pwen vire a. Tout sistèm yo an liy.”
Anèks teknik: Ekwasyon yo
Men ekwasyon kle nou te mansyone nan emisyon an, nan lòd yo parèt la. Afiche yo anba emisyon an sou chak platfòm, ak sou paj ekwasyon yo nan The Equation Agency.
Mizajou desant gradyan (Segman 4)
Kè backpropagation: deplase chak paramèt nan direksyon opoze ak gradyan pèt la.
Aktivasyon ReLU (Segman 4)
Senp, pa lineyè, epi li evite gradyan k ap disparèt.
Koneksyon rezidyèl (Segman 4)
Kite gradyan yo pase dirèkteman atravè kouch yo.
Eta kache RNN (Segman 5)
Trete sekans yo etap pa etap.
Pòtay pou bliye nan LSTM (Segman 5)
Youn nan kat pòtay ki nan yon selil LSTM; se paramèt modèl la aprann yo ki kontwole l.
Atansyon pa pwodui eskalè ki ajiste (Segman 5)
Kè oto-atansyon nan transformer: chak token konsantre sou chak lòt token, an paralèl.
Atansyon plizyè tèt (Segman 5)
Fè h operasyon atansyon an paralèl, epi mete yo bout an bout.
Kodaj pozisyon sinizoyidal (Segman 5)
Mete enfòmasyon sou pozisyon nan atansyon an, paske otreman li pa fè diferans ant pozisyon yo.
Objektif RLHF ak penalite KL (Segman 6)
Optimize pou yon modèl rekonpans, pandan w ap rete pre estrateji (policy) ki te rafine a.
Pwosesis difizyon nan direksyon avan (Segman 7)
Ajoute bri piti piti; modèl la aprann defèt sa.
Kantifikasyon INT8 (Segman 8)
Apwoksime yon pwa an vigil flotan ak yon nonb antye 8 bit epi yon faktè echèl.
Fyabilite konpoze nan sistèm plizyè ajan (Segman 7)
Senk ajan, 90% chak → 59% pou tout chèn nan.
Lis kontwòl pwodiksyon: Pou yo pa koupe son an ankò
Videyo fevriye a te pèdi son li sou yon kopi, e yo te koupe l nan 54:45 sou yon lòt. Etap sa yo pwoteje nouvo vèsyon an.
Pou rezidan Miami-Dade yo
Atik sa a se pou nou li, pataje, epi site. Fwontyè AI a ap avanse pi vit pase enstitisyon yo ka swiv. Mande ofisyèl nou yo twa bagay:
- Ki zouti AI konte nou an deja ap itilize? Fè yo nonmen yo.
- Kiyès ki ka eksplike kijan yo mache? Fè yo eksplike youn.
- Kiyès ki ka etenn yo? Si yo pa ka reponn, zouti yo pa ta dwe ap mache.
Sa se prensip aliyman an nan nivo yon konte. Pataje atik sa a. Poze kesyon yo. Fè yo rann kont.
Transkripsyon konplè emisyon an
Transkripsyon otomatik emisyon an dirèk la (5,994 mo). Mak lè yo louvri videyo a nan moman sa a. Ka gen ti erè nan transkripsyon an.
2:06All right. Hello, hello, hello, hello. Thank you for letting me know. Uh, we're going to be talking about artificial intelligence, architecture, algorithms, and the path of super intelligence. Um, I want to begin with a thought experiment. Uh, I have to repeat this for everyone else, not for Tik Tok. uh because it was not coming out the audio in other streaming. So I want to begin with the thought experiment. Imagine you are sitting in a university library in 1936. Across the table from you is 24 years old graduate student at Cambridge. He's not particularly famous. He has published nothing yet. He's working on a paper about a hypothetical machine. A machine that reads symbols from an infinite tape move left and right, writes new symbols and halts when it reaches a final state. He calls it a universal computer machine. His name is
3:03Alan Turing and the paper he's writing will establish in eight pages a dense mathematic the theoretical foundation for every computer that has ever existed every algorithm you have ever run every neural network you will hear about tonight including the systems they are right now beginning to write their own code reason about novel problems and approach what we might call with appropriate caution general intelligence. So right now tonight happening right now we have machines they are writing codes by themselves. Uh many many years ago we needed software programmers software uh coders to do this. Tonight we have machines doing this by theself. Okay. So I want for you to start getting that uh to see the difference of how everything is shifting from how things were before to where things are going to be. Okay, I choose to begin there because I want you uh everybody you know that is watching I have developers, researchers, engineers, scientists, everyday person people with different backgrounds education no education uh learning starting to learn student college, high school all the way to uh retirement people are watching this uh through Tik Tok, YouTube, kick um X everywhere.
Um I'm I'm choosing to start this here. I have to do something on on different platforms as well. So, uh we I'm going to be working on the computer as as well for just a little bit so I can get everything going. Um, hey. Hello. How are you? Welcome. Welcome. So, I need to see. Yes, they're still doing it. Um All
6:10right. So, we're we're sending a message uh at x.com. Something happened that uh the guys from the Department of Homeland Security that they don't like me doing what I'm doing. They are very u enviate and very minded and obviously they copy a bachelor's degree. Um they they see this uh as a joke for them. But this is very important for everyone as as we move forward here at Because when I used to get uh when I used to post uh from my streaming channels, a message uh will come out directly. Now that is blocked. I need to find out why that is happening. But we'll look for that in another time. It's not important right now. Um, right. So, I choose to begin here because I want you a room. Uh, okay. I want you to to I want you to start here. This is like a lot of people like from developers, researchers, engineers, uh scientists, data scientists, people that are involved in in the segment of artificial intelligence, computing, servers, architecture, etc., etc., etc. to understand that the story we're living through is not new. It's a continuous, the longest running technical project in the history of science. The attempt to make machines that think and we are in the inflection point, not the beginning, not the end, the inflection point, the moment where the curve stop being gradual and becomes in the mathematical sense nearly vertical.
You know, we got rockets, baby, we're going up all the way up. Okay, over the next uh few hours I am going to take you through the entire arc of that story from turning state to
9:04transformer attention mechanism from the perception and perceptron of GPT4 from Marvin Minsky optimism to Gilfrey Hinton's Nobel Prize and his public warnings about extinction risk and then in the final hour I am going to take you to the frontier to AIG to super intelligence that's very important uh to the alignments problem and I am going to be completely honest with you about what we know what we don't know and what the stakes actually are I'm going to assume that you are technical sophisticated I'm going to use uh the real vocabulary procations to taxi gradient descent attention heads, KV cache, uh, RLHF, uh, constitutional AI, mess optimizations, instrumental coverness.
If a term is unfamiliar, stay with me. I will define everything as I introduce it, but I will not dumb this down. Okay? Uh, I I know you guys are very smart. you guys been with me uh in this account and other past accounts and everybody that is watching and following me uh is been getting educated. Uh they are not uh beginners now. Uh we have new developers uh class of 2025. Uh we have new people with new frontiers that they have done it that by themselves. So if you have taken that uh route, I'm very proud of you that you have decided to do something different with your life. Uh so let's start. Okay.
The mathematical and historical foundation, computability, church and turning machine. Okay. To understand AI, you must first understand computation. What it means firmly and precisely for a process to be computable. This is not a soft philosophical question. It is a hard mathematical one and is and it was answered they independently and simultaneously by two people in the mid 1930s to be exact 1936 1937. The first was Alonso Church of Princeton who in 1936 developed lambda calculus a formal system for expression computation in terms of function abstractions and application. church proved the un disability of the anti problem Hbert for decision problem which asked whether there is a general algorithm that can be determined the truth or false posh of any mathematical statement.
The second was churning who developed his model independently and arrive at the same conclusion. His proof used different and arguably more intuitive construction. The machine that reads and
12:03writes symbols on tape turning machine is formally defined as a seven tuple M and a finite set of states uh Q E QF etc etc to to to the cube um a tape alphabet blank symbol input symbols and transition functions an initial state and set of final states the machine reads a symbol transition to a new states write the symbols and move the head left or right. Church and turning together establish what we now call the church turning tasks and function that can be computed by an effective pro procedure by any physical device operating according to deterministic rules can be computed by a turning machine. The store program computed the von Newman architecture emerged directly from this insight. Every computer you have ever used runs in a variant of this architecture. The line from turning abstract machine to your CUDA kernels is directly unbroken.
Now I want to dwell on the halting problem for a moment because it has direct bearing on AI. The halting problem states there is no general algorithm that can determine for an arbitrary program P and arbitrary impute I whether P will or run forever. Turning proof is a beautiful diagonal argument. As soon a machine age solved the halting problem, construct construct a machine D that contradicts age answers about itself and arrive at a contradiction. Therefore, H cannot exist.
Why does this matter for AI? Because if a AI system is turning complete, there will always be questions about its behavior that cannot be answered by examining its code. You cannot always determine in advance what sufficiently power program will do. This has deep implication for AI safety and the alignment problem which we will address in the next few hours. uh the birth of AI. Darth Maul 1956 to the first AI winter.
In the summer of 1956, a group of researchers gathered at Dartmouth College. Among them, John McCarthy, Marvin Minsky, Nathan Roster, and Claude Shan. McCarthy coined the term that will define the field, artificial intelligence. The Dharmoth workshop established the symbolic AI hypothesis. The intelligence is fundamentally the formal manipulation of symbols according to rules. Early results were generally impressive. The logic theorist proved 38 of the 52 theorems in principia mathematica. Elisa simulated a piso therapist so convincely that users for a genuine emotion attachment to it. Users
15:01who knew perfectly well it was a program might seam diagnose bacterial infections using 600 if then rules at levels matching specialist physicians. Excon configure vax vax computer systems and save digital equipment corporation um estimated $25 million per year. But their fundamental problems were insurmountable. First, the knowledge acquisition bottleneck. Beautiful bottleneck that we're still dealing with, but sooner or later we're going to have more bottlenecks. Okay. Building an expert system require extracting knowledge from human experts and encoding it in rules. A slow, expensive, and imperfect process. Expert often cannot articulate their own knowledge.
Michael Planley had identified this as a tactic knowledge problem. AI researcher discover it implicitly and painfully. Let me see if I can like All right. Um fret the knowledge acquisition. Uh second the brightness problem. Experts systems fail catously uh catastrophically outside their training domain. There was no common sense, no ability to reason from first principles, no robustness to unexpected inputs. Third, and most fundamentally, the frame problem formalized by McCarthy and highest on 19 in 1969. How does a system knows what does not change when an action is performed in the real world?
When you pick up a cup, the cup's position changes, but the color of the walls does not. Talking about a cup. Time for a little sip of nice beautiful coffee. How about that? Symbolic system must explicitly represent which fact remain unchanged by each action. And as the number of facts and action grows, this become comp computationally catastrophic. the AI winter pal. The first beginning around 1974 with the light hill report in the United Kingdom. The second in the late 1980s when experts assistant company collapsed. But AI did not die.
It went underground. Real underground. Yeah, baby. And from that period came the research threads that will produce the revolution we're living throughout now. Okay, we're going now to uh move to the statistical term machine learning emerges. The shift that changed
18:01everything was philosophical. Instead of encoding intelligence top down as rules, what is we allow a machine to learn bottom up from the data and experience? The central development was the rediscovery and popularization of back propagation by Roman Hard Hinton and Williams in the landmark in 1986 nature paper. The algorithm applies the chain rule of calculus recursively from the output of a network back to its inputs computing the gradient and the loss with respect to every parameter.
The update rule is simple. is an equation. Okay, I will put all these equations uh down below on all the social medias. So I I'm I'm not going to complicate this. So so it's not hard for everyone. Okay. Uh but the consequence was profound. Multi-layer narrow network could learn their own internal representation of data without being told what those representations should be. the hidden layer develop meaningful features automatically. This was not programmed. It emerged from training. So I'm thinking probably uh I I own the equation agency LLC and I am going to put all these equations on on a website that I'm going to be building so like everybody can can learn about these equations. So I will have like a a separate area on the equation agency LLC website which I I need to like build it up and I'm going to put all these equations in a area so like people can um um learn about some equations. Okay.
The hidden layers develop meaningful features automatically. This was not programmed. It emerges from training. Despite this theoretical advance, the 1980s were dominated by support vector machines uh vapnik and cortes 1995 and assembled methods like random forest and gradient boosted trees. They outperformed neural networks on most benchmarks because they were better matched to the computational resources available. The question was never whether neural networks cool and powerful representations. The 1986 paper had proven they could. The question was whether they could be trained efficiently to and not on data at sufficient scale. The answer came in 2012 and it came from hardware.
Moving for the next section is the image net moment and the GPU revolution. Here's when they come to GPUs. Okay, things are starting to get faster. and more faster thanks to the GPU's revolution. Failey's image net data set
21:021.2 million label images across 1,000 categories and the annual ILOSVRC competition providing the proving ground. In 2010, the best error rate was 28.2%. In 2011, 25.8% incremental steady progress. Then came 2012. Alex Kriski Alia Skeber and Goffrey Hinton submitted Alexnet trained on two Niveia GTX 580 GPUs. Top five error rate 15.3%. So we as as as years climb okay um the error rate declines. So years go error declines. Okay.
Uh next entry 26.2% a margin of nearly 11 percentage points that the entire field had not expected to see for another five or 10 years. Alex Net demonstrated several technique now standard practice uh really activation with the equation FX times equal max time O X which avoid the vanishing gradient and train six time faster than T drop regularization at P equals 0.5 on the fully connected layers data augmentation and GPU training delivering roughly four times Throughout the CPU training, the network has 60 million parameters across five convolutional layers and three fully connected layers.
The cascades of results that follow was extraordinary. VGET showed that matters. Google net introduces multiscales inception models rest nets. Uh he he eat a 2015 introducing connections with another equation h uh * x = x * x + x allowing gradient to follow to flow directly across layers and enabling 52 layers networks. Finally, image nets top uh top errors 3.57% below the estimated human error rate approximately 5%. The machine had learned to see better than we could and the rate had only just begun. Okay.
24:00So, as we move in in in in years, the years go up and the percentage of error, things are getting starting to get more perfect with the years uh that come. Okay. Now we're going to talk about the transformer revolution and the LL era uh sequence modeling before transformers. Give me one second here. Okay. All right. So the transformer revolution and the LM era sequence modeling before transformers language is inherently sequential. The dominant approach through the 2010 was the recurrent neural network. An RNN processes a sequence one token at a time maintaining a hidden state.
HT equals TH NH and the equation is W HH HTUS1 + W XH* X. The problem is back propagation through a multiple by the Jacobian of the hidden state. If the vectoral radius of W hh is less than one gradient vanishes exponentially is greater than one they explodes R and N's fails to learn dependencies across more than 10 to 20 time steps.
27:00LSTM's coach writers and shrine motor on 1997 introduced gating mechanisms are for gate gate. It has another equation, you know, f= o uh wf uh times uh h t -1 * h time xt times plus bf an input gate and sales state that acts as an information highway across many steps. This was a significant improvement but the fundamental bottleneck remain. The bottom bottleneck continues to remain. So as you can see this is like a uh we have we've been dealing with bottlenecks all our lives and eventually eventually there will be no bottlenecks and we're getting very close to that part. Okay.
Um but not attention in 2015 part partially addressed this. The decor could look back at all encoder hidden states and compute a weighted sum but the encoder and decorter were still RRNs. The sequentially dependency remain. Okay. In 2017, Fanwani Shazir Pararoric Jones Gomez Quaser and Poloskin published a paper with a deliberately provocative title. Attention is all you need. Their claim recurrence is necessary. I don't know. attention.
Attention is all you need. Just give me one second. Let me just open something for someone. What am I supposed to say? So um let's see in 2017 uh was sini chaser permer uhi Jones Gomez case here and puliski published a paper with deliberately provocative title attention is all you
30:03need and their claim uh recurrences is unnecessary. Attention alone apply in parallel across the entire sequence is sufficient. They were right. The fundamental operation is scale dot product attention. Attention. K V equals softmax. K Q KT divided V D K and V. Unpack these precisely. Queries. Q and keys K. Compute compility scores. The dot product qt give entry I J as the similarity between curry I and key pushing softmax into low gradient regions. Softman convert scores to attention weight summing to one. We take a weight sum of values. B every token simultaneously acts as a query, a key and a value. Every token can directly attend to every other token. No sequentially dependency, no vanishing gradient, no information and bottleneck.
Multi head attention runs H parallel attention operations with different learn projections. Multi head Q KB equals concat head and head and W O allowing the model to attend to multiple aspects context simultaneously in GPT3 the model equals 12,2838896 heads DK equals 128 points computational complexity is O time N2 times D in sequence length the quadratic scanning that makes long context expensive a flash tension by DAO et 2022 archives the same mathematical result with all times n memory by recording computation to minimize memory bandwidth usage positional encoding addresses the fact that attention is permutation variant.
The original senosio approach PO S2 I equals S I N time POS divided by 10,000 times at 2 I times uh divided D underscore model times period. Motor models use RO O rotary positioning embeddings or alibi.
33:00A full transformer block multi head self attention residual connection plus layer norm position wise feed forward network residual connection plus layer norm and quarter only bird process birectional decoder only GPT uses castle masking each token attend only to previous tokens virtually are frontiers models today GPT4 cloud GML Yama are decoders only transformers. Scoling laws and emergent cap capabilities. In 2020, Kaplan Mckandish Henigan and colleagues at Open AI published scaling laws for neural language models. Performance follows move power laws across many order magnitudes and we continue to get more equations for a fixed computer budget optimal location.
in parameters and in tokens. The chinchillaya paper Hoffman it l and deep min 2022 revise this ratios and and d should scale equally approximately 20 tokens per parameter. GPT3 at 165 billion parameters trained on a 300 billion token was undertrained by his standard Yama 2 at 70 billion parameters trains on two trillion token isa optimal GPT3 training cost an estimated 5 to 10 million dollars. GPT4 is estimated at $100 million or more.
The scallioning law paper gave AI labs a clear empirical rational for investing in ever larger training runs. If loss follows a predictable power law, larger models would reliably perform better with no hard still is invisible at current scales. emerging abilities uh way it uh 2022 documenting capabilities appearing uh discontinuously at threshold scales multi-step artifactic logical deduction analogical reasoning program synthesis chain of thought reasoning emerge around 100 billion parameters in context learning emerged at the few billion the interpretation is condensed Schaffer Uh 2023 argues emergencies emergence is an artifact of discontinuous metrics but the patriarchal phenomenon is not scanning relability produces new capabilities often unanticipated section uh next section instruction toning nhf a pre-trained language model predicts The next token it has no concept of helplessness. The transformation to a
36:09useful assistant required two stages. First a supervised fine-tuning on a human written prompt response demonstration. We algorithm uh 2021 show instruction tune models generalize zero shot to instructions not seen during finetuning outperforming much larger space models. Um second reinforcement learning from human feedback RLHF three stages collect comparison data. Human raiders compare response for given prompt. Train reward model R O of those preferences using the objective mass.
Then optimize the language models against the reward model via PO with the KL differences penalty. So is max uh e * r o * x comma y minus uh b * kl and pi * x parallel tf time x. The KO penalty prevents the model from drifting too far from it supervised fine-tuning behavior preventing reward hacking. The PO clip objective limits excessively large policy updates. The instruct GPT paper show a 13 billion parameter RLHF model was preferred by human evaluators over the raw 175 billion parameter GP3 on the vast majority of prompts. Alignment training dramatically improve perceived quality even when it reduces raw parameter account capabilities and alignment are not in fundamental tensions. Uh constitutional artificial intelligence anthropic approach adds a set of written principles to the process that model critiques and revises it opens output accordingly to those principles. AI feedback R L Aif scales better than pure human evaluation. Shat GPT launched on November 2022. 1 million users in 5 days. 100 million in two months. No consumer technology in history have ever grown that fast. Okay.
So the multimodal models and scientific uh AI. Hey, how you doing everybody on
39:44Okay. Um the current frontier multimodel models and scientific artificial intelligence the transformer architecture generalized beyond text any sequence of tokens will do image patches audio spectral frames video frames protein residues. This architectural university has produced multimodal models that process and generate content across modalities in an integrated way. Flip rap for algorithm at open AI on 2021 trains images and text encoders jointly using contrastive learn contrastive learning. Maximize cosign similarities of machine image text pairs while minimizing non-matching pairs. The result is a shared embedding space where images and their descriptions are geometrically close. Zero shot clip match fully supervised. Next uh restnet 50 on image net without a single label image. The rich semantic structure of language alone provides sufficient supervisory signals.
The future models generate images by learning to reverse anomous process. The forward process and there's another equation uh xt = va * x uh 0 plus v uh 1 - 8 to the T and E progressively adding guine noise. The model learns to predict the noise and at reference start from pure noise and interjectively den noiseise conditions on a text prompt.
42:03Classifier free guidance higher W gives image more faithful to the prompt. Latin diffusions minus stables diffusions minus operates in b a compressed latin space four to eight times more efficient than a pixel space diffusion. Um alpha fold to uh jumper eat algorithm nature 2021 solved the protein folding problem using the e evo former architecture. It process multiple sequence alignments related sequences from across evolutions along with pairwise distant features updating both in a quadruple way. The intuition evolution performed a massive natural experiment and co- variation patterns across species and code threedimensional structures constraint TM score of 0.92 on CAS 14 the data the database now contains predictive structure for over 200 million proteins essentially ever known protein the implications for drug discovery are most significant scientific achievement of this century. So with these equations and all these algorithm, the alpha fall and the jumper algorithm, we're going to have uh more achievements on on on the scientific uh area of on this century. Okay.
Uh, Agentic AI autonomous systems. Okay. This is what is coming next. Um, um, we starting to see those uh, identic AI autonomous systems. We start seeing see vehicles driving themselves. Boats will drive themselves. Airplanes will drive themselves. Everything will drive themselves. Okay. Robots will walk by themselves. Uh, a language model that answers questions is impressive. A language model that plans a sequence of actions used to observe results and revise its plan in pursuit of a goal is something qualitatively different. The react loop ya algorith 2022 interces and actions invocations the model reasons about what to do next.
You know it generates a structure tool calls or receive the observation incorporates it and continues and continues tools used via function called structure JSON schemas define variable
45:00tools the model generate calls and a sandbox execute them. uh results return observation code execution the motors write patent uh the interpreter runs it stands out and stay there return as the next observation multi- aent system decompose task across specialized agents operating in parallel pipelines orchestrators agents architectures a central agent deco composes the task and delegates and relability compounds across agents Five agents uh each at 90% per task give only 59%'s overall success.
Remember these are new things sets as we move forward the overall success 59% start will start coming down as well. Okay. Uh context window managements and memory architecture require explicit engineering. Uh the retrial augmentated generation grounds models in real data documents are encoded as dense embeddings stored in vectors databases pine cone weate chroma and pg vectors and retrive at inference time by co similarity search retry documents are injected into the context windows inside the query advanced rank pipelines at query rewriting Epotellically document embedding, reranking and recusive retriever to improve quality and reduce hallucinations.
The current model landscape and benchmarks GPT4 from open is an estimate mixtures of experts architectures 128,000 tokens context windows top performance of month human evaluation and MMLE GBD4 meaning integrate text vision and audio end to end rather and uh top model of pipelines claw 3.5 sonnet forthropic state-of-the-art on SW bench resolving approximately 40 to 50% of real GitHub issues strong instruction following constitutional AI alignment and active mechanism interpretability research Gemini Ultra from Google deep mind first model 2X6 human expert performance across All 57 MNLU subjects natively model from the ground up.
Show the 57 MMLU subjects
48:05are abstract algebra, anatomy, astronomy, business ethics, clinical knowledge, college biology, college chemistry, college computer science, college mathematics, college medicine, college physics, college security, conceptual physics, ecomtrics, electrical engineering, elementary mathematics, formal logic, global facts, high school biology, high school chemistry, high school computer science, high school European history, high school geography, high school government and politics, microeconomics, mathematics, microeconomics, physics, psychology, statistic, US history and world history, human agent, human and sexuality, international law, Jewish prudence, logical classes, machine learning, management, marketing, medical genetics, ICS, miscellaneous moral disputes, moral scenarios, nutrition, philosophy, prehistory, professional accounting, professional law, professional medicine, professional psychology, public relations, security studies, sociology, US foreign policy, verology, and world religious. So, is one of these are your jobs? Know that you are will be replaced and you are currently already uh will be replaced by artificial intelligence in the next 10 years, five to 10 years because um that's where we are right now.
Um the Yama 3 from meta 70 billion open weight parameters competitive with significantly larger closed model. The existence of powerful open way model has profound implication from research accessibility fine-tuning and the competitive dynamics of the industry benchmarks MLU text knowledge across 57 subjects. the subjects that I just mentioned. GBD4 scores approximately 87% human expert and approximately 89% random baseline 25% human evaluation measures called generations. So uh GPT4 and now we are in GPT 5.2 and we're going to be continue moving uh up as we continue moving our models.
Um GPT4 scores approximately 87%. Okay. Uh and human expert approximately 89% that's B+ on all 57 subjects. Okay. Um humans are expert on few of those subjects. This is scoring overall
51:0389% on GPT4. Now we are on GPT5. So what happens every time that we move from one model to a new model, the model goes up and and and and the percentage of uh the human experts continues to go up. Okay. So so what was B+ becomes a minus and After a minus we comes A+ and after a plus comes super intelligence. Okay. Uh human evolation measure host generation DBT4 achieve uh pass uh at one of approximately 67%.
Uh subswe measure practical software engineering capabilities. Frontier model solve 40 to 50% of verified task. A arc uh AIG AGI designed to require genuine abstract reasoning was below 20% for all frontier models until uh Mini3 achieved 87.5% at high compute. Critical caveat benchmark uh performance and real world utility are imperfectly correlated. Goodart's law applies a measure that becomes a target cease to be good measure. Treat benchmarks numbers as signals not ground truth. Okay.
Uh so so the benchmark numbers are just signals. Okay. So and the signals are that we continue to move models and and the models and the computers continue to evolve and continue to learn and continue to get better. Um what they failed last year and they already learn it. They're not going to commit the same error. So they're going to continue to move forward. Uh artificial intelligence in production infrastructure and inference engineering that's the next subject.
Training frontier models require thousands of GPUs in tight synchronosity. Distributed training strategies. Data parallelism replicates the model and split the data batch. Model parallelism splits the model itself across devices when it does not fit in a single GPU's memory. Tensors parallelism splits individual matrix operations. Pipeline parallelism splits into layers into stages. Numerical precisions uh FP32 for stability. FB16, BF16 for training
54:02efficiency, int8 and ENT for quantitization for inference cost reduction. The KV cache store keys and value projections from all previous process tokens enabling efficient autogressive generations without reprocessing the full context at each step. Imagine managing KB cache memory across thousands of concurrent users require continuous batching and cach eviction and and carefree memory management. Speculative decoding uses a small draft model to generate a candid tokens that the large model then verifies in parallel achieving two to three times throughout input improvement. The co the cost of latency profile of LL inferences measures in tokens per second and dollars per million tokens is a central engineering constraint shaping what applications are feasible. A well quanticized 20 billion parameter open weight model running locally is competitive with club with cloud API calls for many applications at fractions of the ongoing cost.
So when when we're talking about F-32 for stability, FP16 and BF616 for training efficiency, INT8 and ANT4 quantization for inference cost. We're talking about how numbers are represented inside of the GPUs and neural networks. Neuronet networks are just large collections of matrix uh multiplications matrix or multiplications multiplying and adding numbers and billions and trillions of times. Okay. Um one second. So hello hello everybody. How you doing?
So what is a numeric numerical precision? Computers do not store real numbers like humans write them. They they sort approximations using binary flotation points or integer formats. The more bits used to represents a number the more precise it is. The larger range of values it can represent, the more memory it consumes, the lowers
57:00it may be compute. Precision equal tradeoff between accuracy speed memory and cost. So your binary 01 that's what we're talking about here. Okay. FP232 uh and 32-bit floating point is the full precision. One bit for sign uh 8 bit for exponents and 23 bits for mantisa. This give uh seven decimal digits of precision, very wide dynamic range and very strong uh numerical stability. Why we use FP32? Because training neural networks involve uh back propagation, very small gradient values and accumulating tiny updates or millions of steps. If precision is too low, gradients can vanish to zero. Um, and overflow to infinity becomes unsustainable.
Hello. I go I go later on um I go later on to to to co-host and take all the invites. Okay. Uh the downsides four bytes per parameters slows the GPUs compared to low precision for a seven seven billion parameter model 7 billion * 4 bytes equals 280 GB just for weights before optimized states that's massive. Uh the FB16's half precision 16 bit floating point. Uh that's what FP16 means. uh one sign one bit five exponent bits 10 misa bits this means much less precision more much smaller range two bits per parameter have memory of um uh floating point 32 huge advantage uh modern GPUs Nivea tensor cores excuse me are optimized for um floating point 16 math two times memory savings two times The output increase the the problem smaller exponent range uh move to gradient can underflow training can become unstable. The solution is a mixed precision training. In mixed precision for pass in floating point 16, gradients computed in floating point 16 master weight stories on floating point 32 lo scaling prevents underflow. This preserves stability while doubling speed. So BF16's brain floating point uh the BF float 16 is different from floating point 16s. It uses one side bit uh eight exponent bits same as floating point 32 and seven mantis sub bits meaning same dynamic range as floating.32 uh less precision in detail two bytes per parameter. Why this is powerful?
1:00:03Because most Neural networks instability becomes from exponents overflow underflow no for mantisa precision. Um ring floating point 16 keeps the wide range but reduce detail precision that makes it more stable that uh floating point 16 lately as fast easier to train large models with most models LLM training uses uh brain floating 16 uh while lower precision is important training a frontier model thousands of GPUs, weeks of month of compute tens to hundreds of millions of dollars. If you can cut memory in half, double the output and reduce energy cost, you change the economics of AI.
Precision is not a math choice, is a financial decision. uh int8 uh 8 bits quantitization inferences after a model is trained we usually don't need full precision during inferences no back propagation no ranging accumulation just forward pass we can compress weights from floating points to integers int8 means 8 bit ingers one per parameters four times smaller than uh floating point 32 times smaller than floating point 16 brain floating 16 to do this we apply quantization original weight w scales times in into eight value the model stores integer weight scale factor when running in8 times int8 accumulates rescales Modern GPUs support far int8 matrix multiplications. Result two minus four time faster inference. Massive memory saving lower CL cloud cost.
Um the inch for 4bit quantization aggressive compression uses four bits per parameter 0.5 bytes per weight and eight times smaller than uh FP32. This is extremely compact. Use it for running elements locally, edge devices, consumer GPUs and model hardware. Examples, uh 70B parameters, uh FP32 280 GB, BF16 GB, NT8 70 gigabytes, and NT4 35 gigabytes. As you can see, gigabytes
1:03:00start going down. So less gigabytes um you have uh less cost on the server side uh on the equation. Okay. Uh now suddenly consumers GPUs can host large models. Cloud cos dramatically.
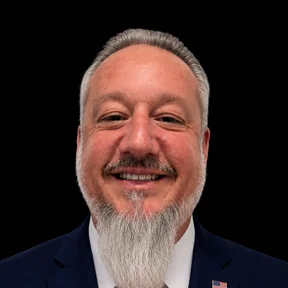
Konsènan Victor J. Rosario
Victor J. Rosario se kandida Rezidan Premye a pou Majistra Konte Miami-Dade 2028. Kòm veteran U.S. Coast Guard, antreprenè, teknolojis, ak atis, Victor pote yon eksperyans ki pwouve nan bati vrè solisyon — soti nan zouti AI rive nan politik kanpay — ki sèvi 2.8 milyon rezidan Miami-Dade yo.
Aprann plis sou Victor