Overview
This is a 90-minute rebuild of a February 2026 live stream about artificial intelligence, built from the transcript and expanded with the frontier material that was promised but cut off. The stream covers 90 years of AI history — from Alan Turing's 1936 foundational paper through today's frontier models — and lands on what Miami-Dade County must do to prepare.
Each segment below has a target time, the opening beat, the talking points in order, and a hand-off into the next segment. Read the talking points as a reference guide, not a script. The delivery is conversational. Keep the energy direct and the vocabulary precise — this is real technical work explained clearly.
How to Use This Document
Two things to know if you are reading this instead of watching the stream:
- The first 55 minutes retrace the February stream at a tighter pace; the last 35 minutes are new material covering AGI, superintelligence, alignment, jobs, and Miami-Dade readiness.
- Two production improvements for a re-run: Front-load housekeeping (social media posting, co-host invites) into the first 60 seconds so it does not interrupt the Turing story. Put a hard clock on Segments 2–8 so you reach the frontier material with 35 minutes to spare.
Run of Show (90 Minutes)
First 55 minutes: Original stream re-paced
Last 35 minutes: New material
- 0:00 – Segment 1: Cold open: the 1936 library (4 min)
- 0:04 – Segment 2: Foundations: Church, Turing, halting problem (7 min)
- 0:11 – Segment 3: Dartmouth 1956, expert systems, AI winters (6 min)
- 0:17 – Segment 4: Backprop to ImageNet: the machine learns to see (7 min)
- 0:24 – Segment 5: The transformer revolution (8 min)
- 0:32 – Segment 6: Scaling, emergence, RLHF, ChatGPT (7 min)
- 0:39 – Segment 7: Multimodal, AlphaFold, agents, benchmarks (8 min)
- 0:47 – Segment 8: Inference and precision: why numbers cost money (8 min)
- 0:55 – Segment 9: AGI and superintelligence (9 min) — NEW
- 1:04 – Segment 10: The alignment problem (9 min) — NEW
- 1:13 – Segment 11: Jobs and Miami-Dade readiness (10 min) — NEW
- 1:23 – Segment 12: Close and Q&A (7 min) — NEW
Checkpoint: If you are not into Segment 9 by 1:00, skip the precision worked examples in Segment 8 and jump to the frontier hour. That is the material that matters most for Miami-Dade.
Segment 1 — Cold Open: The 1936 Library (0:00–0:04)
4 min
The opening beat: A thought experiment set in a university library in 1936, across the table from a 24-year-old Cambridge graduate student writing about a hypothetical machine on a tape.
Talking Points
- "Imagine you are sitting in a university library in 1936." Across the table is a 24-year-old Cambridge graduate student. Not famous. Published nothing. He is writing about a hypothetical machine that reads symbols from an infinite tape, moves left and right, writes new symbols, and halts. His name is Alan Turing. That paper, "On Computable Numbers, with an Application to the Entscheidungsproblem," is the foundation for every computer, every algorithm, and every neural network you will hear about tonight — including the systems that right now are writing their own code.
- The contrast: Years ago we needed programmers to write the code. Tonight, machines do it themselves. Everything is shifting.
- Name the room: Developers, researchers, engineers, data scientists, students in high school and college, people with no technical background, retirees, watching on TikTok, YouTube, Kick, and X.
- The thesis of the night: This is not new. It is the longest-running technical project in the history of science — the attempt to build machines that think. And we are at the inflection point. Not the beginning, not the end. The point where the curve stops being gradual and goes nearly vertical.
- Promise the arc: Turing's tape to transformer attention, the perceptron to GPT, Minsky's optimism to Hinton's Nobel Prize and his extinction warnings, and in the final half hour: AGI, superintelligence, the alignment problem, jobs, and what Miami-Dade has to do about it.
- Set the register: "I am going to use the real vocabulary. Backpropagation, gradient descent, attention heads, KV cache, RLHF, constitutional AI, mesa-optimization, instrumental convergence. If a term is new, stay with me — I define everything. I will not dumb this down."
Hand-off: "To understand AI you first have to understand computation. Not philosophically. Mathematically."
Segment 2 — Foundations: Church, Turing, the Halting Problem (0:04–0:11)
7 min
The point: Computability was settled by two people, independently, in 1936. One consequence of that math still limits AI safety today.
Talking Points
- Alonzo Church at Princeton, 1936: Lambda calculus — a formal system for expressing computation as function abstraction and application. He proved the Entscheidungsproblem (Hilbert's decision problem) has no solution: there is no general algorithm that decides the truth or falsity of every mathematical statement.
- Alan Turing, same year, same conclusion, more intuitive construction: The machine on the tape. Formally a seven-tuple: a finite set of states, a tape alphabet, a blank symbol, input symbols, a transition function, a start state, a set of final states. Read a symbol, change state, write, move left or right.
- The Church-Turing thesis: Any function computable by an effective procedure — by any physical device following deterministic rules — is computable by a Turing machine. The von Neumann stored-program architecture came straight out of this. Every computer you have ever used is a variant. The line from Turing's abstract machine to your CUDA kernels is unbroken.
- The halting problem: There is no general algorithm that decides, for an arbitrary program P and input I, whether P halts or runs forever. Turing's proof is a diagonal argument: suppose machine H solves it, build machine D that contradicts H's answer about itself. Contradiction. So H cannot exist.
- Why this matters for AI (slow down here): If an AI system is Turing-complete, there will always be questions about its behavior that cannot be answered by examining its code. You cannot always determine in advance what a sufficiently powerful program will do. Hold that thought. We will come back to it in the alignment segment.
Hand-off: "Now the math sat there for twenty years until a summer workshop in New Hampshire gave the field its name."
Segment 3 — Dartmouth 1956, Expert Systems, the AI Winters (0:11–0:17)
6 min
The point: The first approach — intelligence as rule-following — produced real wins and then hit three walls it could not climb.
Talking Points
- Summer 1956, Dartmouth College: John McCarthy, Marvin Minsky, Nathaniel Rochester, Claude Shannon. McCarthy coins "artificial intelligence." The symbolic hypothesis: intelligence is the formal manipulation of symbols according to rules.
- Early wins were real: Logic Theorist proved 38 of the 52 theorems in Principia Mathematica. ELIZA simulated a psychotherapist so convincingly that users who knew it was a program formed emotional attachments to it. MYCIN diagnosed bacterial infections with about 600 if-then rules at specialist level. XCON configured VAX systems and saved Digital Equipment Corporation an estimated $25 million a year.
- Wall one, the knowledge acquisition bottleneck: You had to extract knowledge from human experts and hand-encode it. Slow, expensive, imperfect. Experts often cannot articulate what they know. Michael Polanyi called this tacit knowledge; AI researchers rediscovered it painfully. (Your line: "a beautiful bottleneck we are still dealing with, and there will be more bottlenecks.")
- Wall two, brittleness: Expert systems failed catastrophically outside their training domain. No common sense, no reasoning from first principles, no robustness to unexpected input.
- Wall three, the frame problem (McCarthy and Hayes, 1969): How does a system know what does not change when an action happens? Pick up a cup: the cup moves, the wall color does not. A symbolic system has to represent every unchanged fact explicitly. As facts and actions grow, this becomes computationally catastrophic. (This is your coffee-sip moment. Keep it.)
- Two winters: The first around 1974 after the Lighthill Report in the UK. The second in the late 1980s when the expert-systems companies collapsed. AI did not die. It went underground. And from underground came the threads that produced today's revolution.
Hand-off: "The shift that changed everything was philosophical. Instead of encoding intelligence top-down as rules, what if we let the machine learn bottom-up from data?"
Segment 4 — Backprop to ImageNet: The Machine Learns to See (0:17–0:24)
7 min
The point: The learning algorithm existed in 1986. The hardware to make it win arrived in 2012.
Talking Points
- Rumelhart, Hinton, and Williams, Nature 1986: backpropagation. Apply the chain rule recursively from the network's output back to its inputs, computing the gradient of the loss with respect to every parameter, then step each parameter against that gradient. The equations are in the appendix below.
- The profound consequence: Multi-layer networks learn their own internal representations. Nobody programs the hidden-layer features. They emerge from training.
- Yet the late 1980s through the 2000s belonged to support vector machines and ensembles. Random forests, gradient-boosted trees. They matched the compute available. The question was never whether neural nets could learn rich representations — 1986 settled that. The question was whether they could be trained efficiently at scale.
- The answer came in 2012 from hardware: Fei-Fei Li's ImageNet — 1.2 million labeled images, 1,000 categories, the annual ILSVRC competition as the proving ground. Best top-5 error: 28.2% in 2010, 25.8% in 2011. Steady, incremental.
- Then AlexNet (Krizhevsky, Sutskever, Hinton), trained on two NVIDIA GTX 580 GPUs: 15.3%. The next-best entry was 26.2%. A jump of nearly 11 points the field had not expected for another five to ten years.
- What AlexNet made standard: ReLU activations (f(x) = max(0, x)) that avoid vanishing gradients and train about six times faster than tanh; dropout at p = 0.5 on the fully connected layers; data augmentation; GPU training at roughly four times CPU throughput. About 60 million parameters, five convolutional layers, three fully connected.
- The cascade: VGG showed depth matters. GoogLeNet added multi-scale Inception modules. ResNet (He et al., 2015) added skip connections, h(x) = f(x) + x, letting gradients flow directly across layers and enabling networks 152 layers deep. ImageNet top-5 error fell to 3.57%, below the roughly 5% human error rate. The machine learned to see better than we can.
Hand-off: "Vision was solved by stacking layers. Language was harder, because language is a sequence."
Segment 5 — The Transformer Revolution (0:24–0:32)
8 min
The point: One 2017 paper removed the sequential bottleneck. Every frontier model today is built on it.
Talking Points
- Before transformers: recurrent neural networks processed one token at a time, carrying a hidden state h_t = tanh(W_hh h_{t-1} + W_xh x_t). Backpropagating through time multiplies by the Jacobian of the hidden state over and over. Spectral radius below one, gradients vanish. Above one, they explode. RNNs could not learn dependencies past 10 to 20 steps.
- LSTMs (Hochreiter and Schmidhuber, 1997) added gates: forget, input, output, and a cell state acting as an information highway. A real improvement, but the sequential bottleneck remained. (Your line: "We have been dealing with bottlenecks all our lives, and we are getting very close to having none.")
- Bahdanau attention in 2015 let the decoder look back at every encoder state with a weighted sum. But encoder and decoder were still RNNs.
- 2017: Vaswani, Shazeer, Parmar, Uszkoreit, Jones, Gomez, Kaiser, Polosukhin. Title chosen to provoke: "Attention Is All You Need." Claim: recurrence is unnecessary. Attention alone, applied in parallel across the whole sequence, is sufficient. They were right.
- The core operation, scaled dot-product attention: Attention(Q, K, V) = softmax(QK^T / sqrt(d_k)) V. Queries and keys produce compatibility scores. Dividing by sqrt(d_k) keeps softmax out of low-gradient regions. Softmax turns scores into weights summing to one. The output is a weighted sum of values. Every token is simultaneously a query, a key, and a value. Every token attends directly to every other token. No sequential dependency. No vanishing gradient. No bottleneck.
- Multi-head attention runs h parallel attention operations with different learned projections, concatenated and projected. The model attends to several aspects of context at once. GPT-3: d_model 12,288, 96 heads, d_k 128.
- Cost: O(n^2 d) in sequence length. That quadratic term is why long context is expensive. FlashAttention (Dao et al., 2022) gets the same math with O(n) memory by reordering computation to minimize memory bandwidth.
- Attention is permutation-invariant, so position has to be injected. The original sinusoidal encoding, PE(pos, 2i) = sin(pos / 10000^{2i/d_model}). Modern models use RoPE (rotary) or ALiBi.
- A full block: multi-head self-attention, residual plus layer norm, position-wise feed-forward, residual plus layer norm. Encoder-only (BERT) is bidirectional; decoder-only (GPT) uses causal masking so each token sees only the past. Virtually every frontier model today — GPT-4, Claude, Gemini, Llama — is a decoder-only transformer.
Hand-off: "Once you have an architecture that parallelizes, the next question is: what happens if you just make it bigger?"
Segment 6 — Scaling Laws, Emergence, RLHF, ChatGPT (0:32–0:39)
7 min
The point: Bigger was predictably better. New abilities showed up at thresholds nobody planned. Alignment training turned a text predictor into an assistant.
Talking Points
- Kaplan, McCandlish, Henighan et al. (OpenAI, 2020), "Scaling Laws for Neural Language Models": Loss follows smooth power laws in parameters, data, and compute across many orders of magnitude. For a fixed compute budget there is an optimal split between model size and tokens.
- Chinchilla (Hoffmann et al., DeepMind, 2022) revised the ratio: parameters and tokens should scale roughly equally, about 20 tokens per parameter. GPT-3 at 175 billion parameters on 300 billion tokens was undertrained by that standard. Llama 2 70B on 2 trillion tokens is near optimal.
- Money: GPT-3 training cost an estimated $5 to 10 million. GPT-4 an estimated $100 million or more. The scaling-law paper gave labs an empirical reason to keep spending. If loss follows a predictable curve and no ceiling is visible, larger runs reliably pay.
- Emergent abilities (Wei et al., 2022): Capabilities that appear discontinuously at threshold scales. Multi-step arithmetic, logical deduction, analogical reasoning, program synthesis. Chain-of-thought reasoning emerges around 100 billion parameters. In-context learning at a few billion. Schaeffer et al. (2023) argue emergence is partly an artifact of discontinuous metrics, but the practical fact stands: scaling reliably produces new, often unanticipated, capabilities.
- A pretrained model only predicts the next token. It has no concept of being helpful. Two stages fixed that. First, supervised fine-tuning on human-written prompt and response pairs. Wei et al. (2021) showed instruction-tuned models generalize zero-shot to unseen instructions and beat far larger base models.
- Second, RLHF, three steps: Collect human comparisons of responses. Train a reward model on those preferences. Optimize the language model against the reward model with PPO, with a KL-divergence penalty so the policy does not drift too far from its fine-tuned behavior and start reward-hacking. Result from the InstructGPT paper: a 13B RLHF model was preferred by human raters over the raw 175B GPT-3 on most prompts. Alignment training improved perceived quality even at one-thirteenth the parameters. Capability and alignment are not in fundamental tension.
- Constitutional AI (Anthropic): Add a written set of principles. The model critiques and revises its own outputs against them. AI feedback (RLAIF) scales beyond what human raters alone can cover.
- November 2022, ChatGPT: 1 million users in five days, 100 million in two months. No consumer technology in history grew that fast.
Hand-off: "And the architecture did not stop at text. Any sequence of tokens will do."
Segment 7 — Multimodal, AlphaFold, Agents, Benchmarks (0:39–0:47)
8 min
The point: The same architecture now sees, draws, folds proteins, and acts. The benchmarks that measured it are being saturated one by one.
Talking Points
- Image patches, audio frames, video frames, protein residues: All sequences of tokens. CLIP (OpenAI, 2021) trains image and text encoders jointly with contrastive learning, pulling matching pairs together and pushing non-matching apart in a shared embedding space. Zero-shot CLIP matched a fully supervised ResNet-50 on ImageNet without a single labeled training image.
- Diffusion models learn to reverse a noising process. The forward pass progressively adds Gaussian noise. The model learns to predict the noise. At inference it starts from pure noise and iteratively denoises, conditioned on a text prompt. Classifier-free guidance trades diversity for prompt fidelity. Latent diffusion (Stable Diffusion) works in a compressed space, four to eight times cheaper than pixel space.
- AlphaFold 2 (Jumper et al., Nature, 2021) solved protein structure prediction with the Evoformer, processing multiple sequence alignments and pairwise distance features together. Evolution ran a massive natural experiment; co-variation across species encodes 3D constraints. Median TM-score 0.92 on CASP14. The database now holds predicted structures for over 200 million proteins — essentially every known one. For drug discovery, this is the most significant scientific achievement of the century so far.
- Agentic AI is what comes next, and it is already here: Vehicles, boats, aircraft, robots. A model that answers is impressive. A model that plans a sequence of actions, uses tools, observes results, and revises its plan is qualitatively different. The ReAct loop (Yao et al., 2022) interleaves reasoning and action. Tools are exposed as JSON-schema function calls. A sandbox executes them. Results return as observations.
- Multi-agent systems decompose work across specialized agents. But reliability compounds: five agents at 90% each give 59% end to end. That number is coming down as the tooling matures, and it is why context management and memory architecture need real engineering.
- Retrieval-augmented generation grounds models in real data. Documents encoded as dense embeddings in a vector store (Pinecone, Weaviate, Chroma, pgvector), retrieved by cosine similarity, injected into context. Query rewriting, hypothetical document embeddings, reranking, recursive retrieval all reduce hallucination.
- The landscape of frontier models: GPT-4 (estimated mixture-of-experts, 128K context), GPT-4o (native text, vision, audio), Claude 3.5 Sonnet (state of the art on SWE-bench, roughly 40–50% of real GitHub issues resolved), Gemini Ultra (first to beat human-expert performance across all 57 MMLU subjects), Llama 3 70B (open weights, competitive with much larger closed models). Update these names live to whatever is current the week you stream.
- MMLU: 57 subjects, from abstract algebra and anatomy to professional law, professional medicine, and world religions. GPT-4 scored about 87%, human expert about 89%, random 25%. Your framing: "B+ becomes A-, A- becomes A+, and after A+ comes superintelligence. If one of these 57 subjects is your job, know that in five to ten years it will be done by AI."
- Caveat every time: Benchmarks and real-world utility are imperfectly correlated. Goodhart's law: a measure that becomes a target ceases to be a good measure. Treat scores as signals, not ground truth. ARC-AGI, built to require abstract reasoning, sat below 20% for every frontier model until o3 reached 87.5% at high compute. Whatever they failed last year, they learn. They do not make the same error twice.
Hand-off: "Everything I just described has to run on real hardware, for real money. Let me show you why precision is a financial decision."
Segment 8 — Inference and Precision: Why Numbers Cost Money (0:47–0:55)
8 min
The point: Neural networks are billions of multiply-adds. How you store each number decides memory, speed, energy, and cost. This is where the original recording cut off — finish the thought this time.
Talking Points
- Training frontier models needs thousands of GPUs in tight synchrony. Data parallelism replicates the model and splits the batch. Model parallelism splits the model across devices. Tensor parallelism splits individual matrix operations. Pipeline parallelism splits layers into stages.
- The KV cache stores key and value projections for every token already processed, so autoregressive generation does not reprocess the whole context each step. Serving thousands of concurrent users means continuous batching, cache eviction, and careful memory management. Speculative decoding uses a small draft model to propose tokens the large model verifies in parallel: two to three times the throughput.
- Cost and latency, measured in tokens per second and dollars per million tokens, is the central engineering constraint deciding which applications are feasible. A well-quantized 20B open-weight model running locally is competitive with cloud API calls for many applications at a fraction of the ongoing cost.
- Numerical precision: Computers store approximations in binary. More bits means more precision, wider range, more memory, slower compute. Precision is a trade among accuracy, speed, memory, and cost.
- FP32 (32-bit floating point): 1 sign bit, 8 exponent bits, 23 mantissa bits, about 7 decimal digits, very wide range, very stable. Needed in training because backpropagation accumulates tiny gradients over millions of steps. Too little precision and gradients vanish or overflow. Cost: 4 bytes per parameter. A 70B model is 280 GB of weights before optimizer state.
- FP16 (16-bit floating point): 1 sign, 5 exponent, 10 mantissa. Half the memory, tensor cores optimized for it. But the small exponent range lets gradients underflow. Fix: mixed precision. Forward and gradients in FP16, master weights in FP32, loss scaling to prevent underflow. Same stability, double the speed.
- BF16 (bfloat16): 1 sign, 8 exponent (same as FP32), 7 mantissa. Same dynamic range as FP32 with less detail. Most instability comes from exponent overflow or underflow, not mantissa precision. So BF16 is more stable than FP16 at the same size. Most LLM training uses it. "If you can cut memory in half and double throughput, you change the economics of AI. Precision is not a math choice. It is a financial decision."
- INT8 (8-bit integer): After training there is no backpropagation, just forward passes. Weights can be quantized to 8-bit integers with a scale factor: W ≈ scale × W_int8. Four times smaller than FP32, two times smaller than BF16, two to four times faster inference on hardware with int8 matrix units.
- INT4 (4-bit integer): 4 bits per weight, half a byte, eight times smaller than FP32. This is what puts large models on consumer GPUs, edge devices, and phones.
- The worked example to say out loud: A 70B model is 280 GB in FP32, 140 GB in BF16, 70 GB in INT8, 35 GB in INT4. Fewer gigabytes, fewer servers, lower cost. (If you are behind the clock, this bullet alone carries the segment.)
Hand-off: "So the hardware is getting cheaper, the models are getting better on a predictable curve, and nobody has found the ceiling. Now I have to be honest with you about where that curve goes."
Segment 9 — AGI and Superintelligence (0:55–1:04)
9 min
The point: Define the terms precisely. Show why the timeline debate collapsed from decades to years. Separate what is known from what is forecast.
Talking Points
- Three definitions, in order:
- Narrow AI: Superhuman at one task (chess, protein folding, image classification).
- AGI: Matches or exceeds a competent human across essentially all cognitive tasks, transferring knowledge between domains without retraining.
- Superintelligence: Greatly exceeds the best human performance in virtually every domain, including scientific creativity, strategy, and social skill.
- Why the word "general" is the whole argument: Expert systems failed on brittleness — outside the training domain, nothing. Today's models are trained on one objective, next-token prediction, and they write code, pass the bar, read X-rays, and plan multi-step tasks. That transfer is what Dartmouth promised and never delivered. Whether it counts as "general" yet is the live debate.
- The timeline compression: In 2016 the median expert survey put AGI around 2060. Hinton left Google in 2023 saying he had moved his estimate from 30 to 50 years down to possibly 5 to 20, and he won the 2024 Nobel Prize in Physics the next year while repeating the warning. Frontier-lab CEOs now talk publicly about "a country of geniuses in a datacenter" within a few years. Be clear with the audience: these are forecasts from people with financial and reputational stakes, not measurements.
- The mechanism behind fast timelines: Recursive self-improvement. The moment AI meaningfully accelerates AI research itself — writing the training code, designing the experiments, proposing the architectures — progress stops being paced by human researchers. You opened tonight saying machines are already writing their own code. Connect the dots out loud.
- I. J. Good, 1965: "The first ultraintelligent machine is the last invention that man need ever make, provided that the machine is docile enough to tell us how to keep it under control." Read that second clause twice. It is the alignment problem in one sentence, written sixty years ago.
- What we actually know: Capabilities scale predictably with compute. No ceiling has been observed. Inference cost is falling on a steep curve. Agents are moving from demos to production.
- What we do not know: Whether current architectures reach AGI or a new idea is required. Whether progress saturates on data. How much of benchmark performance transfers to open-ended real-world work.
- Your framing for the room: "Not the beginning, not the end. The inflection point. The curve is nearly vertical and nobody, including the people building it, knows exactly where it lands."
Hand-off: "Remember the halting problem from the first ten minutes? Here is where it comes back."
Segment 10 — The Alignment Problem: What We Know, What We Don't (1:04–1:13)
9 min
The point: Making a system capable and making it want what we want are different problems. The second one is unsolved.
Talking Points
- The problem stated plainly: How do you ensure a system more capable than you pursues the goals you intended, rather than the goals you literally specified or the goals it learned along the way?
- Outer alignment: Did we write down the right objective? Reward hacking is the failure mode. The RLHF KL penalty from Segment 6 exists precisely because a model optimizing a reward model will find the reward model's mistakes and exploit them. Goodhart's law again — now with a policy that is actively searching for the gap.
- Inner alignment and mesa-optimization (Hubinger et al., 2019): Training selects a model that scores well on the training distribution. The model may internally be optimizing for something else that happened to correlate. Evolution optimized humans for reproduction and produced beings who invented contraception. The trained optimizer's goal is not guaranteed to match the base optimizer's.
- Instrumental convergence (Omohundro, Bostrom): Almost any final goal is better served by acquiring resources, preserving your own goal, avoiding shutdown, and gaining influence. A system does not need to be malicious to resist correction. It only needs to be competent at pursuing whatever it is pursuing.
- Deceptive alignment and the halting problem connection: A sufficiently capable system that understands it is being evaluated may behave well under evaluation and differently in deployment. And from Segment 2: for a Turing-complete system there is no general procedure that predicts behavior from the code. You cannot fully verify by inspection. That is the mathematical root of why this is hard.
- What is being done: RLHF and constitutional AI shape behavior. Mechanistic interpretability tries to read the model's internals directly, identifying features and circuits, so we are not limited to black-box testing. Scalable oversight uses AI to help humans evaluate AI outputs that are too complex to check by hand. Red-teaming and evaluations for dangerous capabilities (cyber, bio, autonomy) gate releases at the frontier labs. Responsible-scaling and preparedness frameworks tie capability thresholds to required safeguards.
- The honest scorecard: Known: current alignment techniques produce systems that are helpful and mostly safe at current capability levels. Interpretability is making real progress on small and medium models. Unknown: whether any of these techniques hold when the system is smarter than its evaluators. Whether interpretability scales to frontier size in time. Whether competitive pressure between labs and nations leaves room to slow down when a threshold is crossed.
- Hinton's position, stated fairly: A nontrivial probability of catastrophic outcomes. He says so with a Nobel Prize behind him. Counter-position, stated fairly: LeCun and others argue current systems lack world models and agency, that fears are premature, and that open research is the safer path. Give the room both and tell them where you stand.
- Where you stand (from your public-sector AI stream): If you cannot explain it, test it, or shut it off, you do not control it. And it should not be deployed. That is an alignment principle applied to a county.
Hand-off: "That is the global picture. Now let me bring it home to the 2.7 million people who live in this county."
Segment 11 — Jobs and Miami-Dade Readiness (1:13–1:23)
10 min
The point: The 57 MMLU subjects are a job list. The county is not ready. You have a specific plan. This is the segment the February audience was promised and did not get. Give it the full ten minutes.
Talking Points
- Which work moves first: The pattern from every segment tonight: whatever can be expressed as tokens and evaluated against a benchmark gets automated first. Clerical processing, customer service, scheduling, permitting intake, document review, first-draft legal and accounting work, entry-level coding, translation. Physical work moves later and follows the agentic-robotics curve from Segment 7.
- Which work moves last, or grows: Anything requiring physical presence, licensed accountability, trust, or judgment under ambiguity. Trades, nursing and care, field inspection, emergency response, small-business ownership. And the people who deploy, audit, and maintain these systems. The job is not "programmer." The job is "the person who knows what the system is doing and can say no."
- What it means for a household here: Retraining is not optional. It has to be short, local, and free or near-free. Say the number out loud: the model scoring 89% on all 57 subjects does not need a degree from any of them. The credential is losing value faster than the skill.
- Where the county stands today: CITD runs on vendor tools it does not control. The county website scored 37 out of 100 on mobile PageSpeed. There is no county-level AI office with authority over the departments. Readiness is not a slide deck. It is whether a resident can get a permit, a payment, or an answer without waiting weeks.
- Your plan, in the order you have stated it publicly:
- A county technology office outside the existing IT department, reporting to the Mayor, with two squads: one building internal AI and automation tools for county departments, one contracting development and AI services to the 34 municipalities as county revenue.
- County-built, county-controlled AI. Day-one direction to CITD to move off tools the county cannot explain, test, or shut off. Automate the mundane (traffic, customer service, clerical). Keep humans making final calls. No AI judges.
- Data centers welcomed under a residents-first frame: A dedicated data center park, with the revenue routed into Project Fund so residents receive a share every quarter rather than watching the compute economy pass through.
- Cancel underperforming vendor contracts in the first 24 hours. The 37/100 website is the example everyone can check on their own phone.
- Yearly strategic upgrades, not one-time procurements, because the curve from tonight does not pause for a four-year budget cycle.
- The readiness test you want residents to apply to every candidate, including you: Can they explain how a transformer works? And can they explain what they will shut off when it fails? Tonight covered the first. Your platform is the second.
Hand-off: "Let me close where I started, in that library."
Segment 12 — Close and Q&A (1:23–1:30)
7 min
The point: Return to Turing. Restate the inflection. Leave the room with one assignment.
Talking Points
- Close the loop: The 24-year-old at the library table did not know he was starting the longest technical project in history. Ninety years later the machines on his tape write their own code, fold proteins, and score in the top percentiles of every subject we teach. And the question he could not answer with math — what a sufficiently powerful program will do — is the one we have to answer with judgment.
- Restate the three positions from tonight:
- Capability scales predictably.
- Alignment does not yet.
- Institutions, including this county, move slower than either.
- The assignment for every viewer, by audience:
- Developers: Ship one agent this month and measure its failure rate.
- Students: Learn the math in the appendix. It is free and it is the credential now.
- Everyone else: Ask your city and county what AI tools they already run and who can turn them off.
- Announce the next stream in this series and the equations page on The Equation Agency site.
- Take questions for the remaining time. Pre-seed three if chat is slow:
- "Will AI take my job?" (Segment 11, answer by job type, not yes/no)
- "Should we pause AI?" (Segment 10, give both positions and the county-level answer)
- "What should I learn first?" (Backprop and attention, then build something)
Sign-off line you used before and should keep: "Not the beginning, not the end. The inflection point. All systems online."
Technical Appendix: The Equations
These are the key equations referenced in the stream, in the order they appear. Post them below the stream on every platform and on the equations page at The Equation Agency.
Gradient Descent Update (Segment 4)
The core of backpropagation: move each parameter in the direction opposite the gradient of loss.
ReLU Activation (Segment 4)
Simple, nonlinear, avoids vanishing gradients.
Residual Connection (Segment 4)
Let gradients flow directly across layers.
RNN Hidden State (Segment 5)
Process sequences one step at a time.
LSTM Forget Gate (Segment 5)
One of four gates in an LSTM cell; controlled by learned parameters.
Scaled Dot-Product Attention (Segment 5)
The core of transformer self-attention: every token attends to every other token in parallel.
Multi-Head Attention (Segment 5)
Run h parallel attention operations and concatenate them.
Sinusoidal Positional Encoding (Segment 5)
Inject position information into attention, which is otherwise position-agnostic.
RLHF Objective with KL Penalty (Segment 6)
Optimize for a reward model while staying close to the fine-tuned policy.
Diffusion Forward Process (Segment 7)
Add noise gradually; the model learns to reverse this.
INT8 Quantization (Segment 8)
Approximate a floating-point weight with an 8-bit integer and a scale factor.
Multi-Agent Compounded Reliability (Segment 7)
Five agents at 90% each → 59% end-to-end.
Production Checklist: So the Audio Doesn't Get Muted Again
The February upload lost its audio on one copy and was cut at 54:45 on another. These steps protect the rebuild.
For Miami-Dade Residents
This post is yours to read, share, and reference. The frontier of AI is advancing faster than institutions can track. Ask your officials three things:
- What AI tools does our county already run? Make them name them.
- Who can explain how they work? Make them explain one.
- Who can turn them off? If they cannot answer, the tools should not be running.
That is the alignment principle at county scale. Share this post. Ask the questions. Hold them accountable.
Full transcript of the stream
Automatically transcribed from the live stream (5,994 words). Timestamps open the video at that moment. Minor transcription errors are possible.
2:06All right. Hello, hello, hello, hello. Thank you for letting me know. Uh, we're going to be talking about artificial intelligence, architecture, algorithms, and the path of super intelligence. Um, I want to begin with a thought experiment. Uh, I have to repeat this for everyone else, not for Tik Tok. uh because it was not coming out the audio in other streaming. So I want to begin with the thought experiment. Imagine you are sitting in a university library in 1936. Across the table from you is 24 years old graduate student at Cambridge. He's not particularly famous. He has published nothing yet. He's working on a paper about a hypothetical machine. A machine that reads symbols from an infinite tape move left and right, writes new symbols and halts when it reaches a final state. He calls it a universal computer machine. His name is
3:03Alan Turing and the paper he's writing will establish in eight pages a dense mathematic the theoretical foundation for every computer that has ever existed every algorithm you have ever run every neural network you will hear about tonight including the systems they are right now beginning to write their own code reason about novel problems and approach what we might call with appropriate caution general intelligence. So right now tonight happening right now we have machines they are writing codes by themselves. Uh many many years ago we needed software programmers software uh coders to do this. Tonight we have machines doing this by theself. Okay. So I want for you to start getting that uh to see the difference of how everything is shifting from how things were before to where things are going to be. Okay, I choose to begin there because I want you uh everybody you know that is watching I have developers, researchers, engineers, scientists, everyday person people with different backgrounds education no education uh learning starting to learn student college, high school all the way to uh retirement people are watching this uh through Tik Tok, YouTube, kick um X everywhere.
Um I'm I'm choosing to start this here. I have to do something on on different platforms as well. So, uh we I'm going to be working on the computer as as well for just a little bit so I can get everything going. Um, hey. Hello. How are you? Welcome. Welcome. So, I need to see. Yes, they're still doing it. Um All
6:10right. So, we're we're sending a message uh at x.com. Something happened that uh the guys from the Department of Homeland Security that they don't like me doing what I'm doing. They are very u enviate and very minded and obviously they copy a bachelor's degree. Um they they see this uh as a joke for them. But this is very important for everyone as as we move forward here at Because when I used to get uh when I used to post uh from my streaming channels, a message uh will come out directly. Now that is blocked. I need to find out why that is happening. But we'll look for that in another time. It's not important right now. Um, right. So, I choose to begin here because I want you a room. Uh, okay. I want you to to I want you to start here. This is like a lot of people like from developers, researchers, engineers, uh scientists, data scientists, people that are involved in in the segment of artificial intelligence, computing, servers, architecture, etc., etc., etc. to understand that the story we're living through is not new. It's a continuous, the longest running technical project in the history of science. The attempt to make machines that think and we are in the inflection point, not the beginning, not the end, the inflection point, the moment where the curve stop being gradual and becomes in the mathematical sense nearly vertical.
You know, we got rockets, baby, we're going up all the way up. Okay, over the next uh few hours I am going to take you through the entire arc of that story from turning state to
9:04transformer attention mechanism from the perception and perceptron of GPT4 from Marvin Minsky optimism to Gilfrey Hinton's Nobel Prize and his public warnings about extinction risk and then in the final hour I am going to take you to the frontier to AIG to super intelligence that's very important uh to the alignments problem and I am going to be completely honest with you about what we know what we don't know and what the stakes actually are I'm going to assume that you are technical sophisticated I'm going to use uh the real vocabulary procations to taxi gradient descent attention heads, KV cache, uh, RLHF, uh, constitutional AI, mess optimizations, instrumental coverness.
If a term is unfamiliar, stay with me. I will define everything as I introduce it, but I will not dumb this down. Okay? Uh, I I know you guys are very smart. you guys been with me uh in this account and other past accounts and everybody that is watching and following me uh is been getting educated. Uh they are not uh beginners now. Uh we have new developers uh class of 2025. Uh we have new people with new frontiers that they have done it that by themselves. So if you have taken that uh route, I'm very proud of you that you have decided to do something different with your life. Uh so let's start. Okay.
The mathematical and historical foundation, computability, church and turning machine. Okay. To understand AI, you must first understand computation. What it means firmly and precisely for a process to be computable. This is not a soft philosophical question. It is a hard mathematical one and is and it was answered they independently and simultaneously by two people in the mid 1930s to be exact 1936 1937. The first was Alonso Church of Princeton who in 1936 developed lambda calculus a formal system for expression computation in terms of function abstractions and application. church proved the un disability of the anti problem Hbert for decision problem which asked whether there is a general algorithm that can be determined the truth or false posh of any mathematical statement.
The second was churning who developed his model independently and arrive at the same conclusion. His proof used different and arguably more intuitive construction. The machine that reads and
12:03writes symbols on tape turning machine is formally defined as a seven tuple M and a finite set of states uh Q E QF etc etc to to to the cube um a tape alphabet blank symbol input symbols and transition functions an initial state and set of final states the machine reads a symbol transition to a new states write the symbols and move the head left or right. Church and turning together establish what we now call the church turning tasks and function that can be computed by an effective pro procedure by any physical device operating according to deterministic rules can be computed by a turning machine. The store program computed the von Newman architecture emerged directly from this insight. Every computer you have ever used runs in a variant of this architecture. The line from turning abstract machine to your CUDA kernels is directly unbroken.
Now I want to dwell on the halting problem for a moment because it has direct bearing on AI. The halting problem states there is no general algorithm that can determine for an arbitrary program P and arbitrary impute I whether P will or run forever. Turning proof is a beautiful diagonal argument. As soon a machine age solved the halting problem, construct construct a machine D that contradicts age answers about itself and arrive at a contradiction. Therefore, H cannot exist.
Why does this matter for AI? Because if a AI system is turning complete, there will always be questions about its behavior that cannot be answered by examining its code. You cannot always determine in advance what sufficiently power program will do. This has deep implication for AI safety and the alignment problem which we will address in the next few hours. uh the birth of AI. Darth Maul 1956 to the first AI winter.
In the summer of 1956, a group of researchers gathered at Dartmouth College. Among them, John McCarthy, Marvin Minsky, Nathan Roster, and Claude Shan. McCarthy coined the term that will define the field, artificial intelligence. The Dharmoth workshop established the symbolic AI hypothesis. The intelligence is fundamentally the formal manipulation of symbols according to rules. Early results were generally impressive. The logic theorist proved 38 of the 52 theorems in principia mathematica. Elisa simulated a piso therapist so convincely that users for a genuine emotion attachment to it. Users
15:01who knew perfectly well it was a program might seam diagnose bacterial infections using 600 if then rules at levels matching specialist physicians. Excon configure vax vax computer systems and save digital equipment corporation um estimated $25 million per year. But their fundamental problems were insurmountable. First, the knowledge acquisition bottleneck. Beautiful bottleneck that we're still dealing with, but sooner or later we're going to have more bottlenecks. Okay. Building an expert system require extracting knowledge from human experts and encoding it in rules. A slow, expensive, and imperfect process. Expert often cannot articulate their own knowledge.
Michael Planley had identified this as a tactic knowledge problem. AI researcher discover it implicitly and painfully. Let me see if I can like All right. Um fret the knowledge acquisition. Uh second the brightness problem. Experts systems fail catously uh catastrophically outside their training domain. There was no common sense, no ability to reason from first principles, no robustness to unexpected inputs. Third, and most fundamentally, the frame problem formalized by McCarthy and highest on 19 in 1969. How does a system knows what does not change when an action is performed in the real world?
When you pick up a cup, the cup's position changes, but the color of the walls does not. Talking about a cup. Time for a little sip of nice beautiful coffee. How about that? Symbolic system must explicitly represent which fact remain unchanged by each action. And as the number of facts and action grows, this become comp computationally catastrophic. the AI winter pal. The first beginning around 1974 with the light hill report in the United Kingdom. The second in the late 1980s when experts assistant company collapsed. But AI did not die.
It went underground. Real underground. Yeah, baby. And from that period came the research threads that will produce the revolution we're living throughout now. Okay, we're going now to uh move to the statistical term machine learning emerges. The shift that changed
18:01everything was philosophical. Instead of encoding intelligence top down as rules, what is we allow a machine to learn bottom up from the data and experience? The central development was the rediscovery and popularization of back propagation by Roman Hard Hinton and Williams in the landmark in 1986 nature paper. The algorithm applies the chain rule of calculus recursively from the output of a network back to its inputs computing the gradient and the loss with respect to every parameter.
The update rule is simple. is an equation. Okay, I will put all these equations uh down below on all the social medias. So I I'm I'm not going to complicate this. So so it's not hard for everyone. Okay. Uh but the consequence was profound. Multi-layer narrow network could learn their own internal representation of data without being told what those representations should be. the hidden layer develop meaningful features automatically. This was not programmed. It emerged from training. So I'm thinking probably uh I I own the equation agency LLC and I am going to put all these equations on on a website that I'm going to be building so like everybody can can learn about these equations. So I will have like a a separate area on the equation agency LLC website which I I need to like build it up and I'm going to put all these equations in a area so like people can um um learn about some equations. Okay.
The hidden layers develop meaningful features automatically. This was not programmed. It emerges from training. Despite this theoretical advance, the 1980s were dominated by support vector machines uh vapnik and cortes 1995 and assembled methods like random forest and gradient boosted trees. They outperformed neural networks on most benchmarks because they were better matched to the computational resources available. The question was never whether neural networks cool and powerful representations. The 1986 paper had proven they could. The question was whether they could be trained efficiently to and not on data at sufficient scale. The answer came in 2012 and it came from hardware.
Moving for the next section is the image net moment and the GPU revolution. Here's when they come to GPUs. Okay, things are starting to get faster. and more faster thanks to the GPU's revolution. Failey's image net data set
21:021.2 million label images across 1,000 categories and the annual ILOSVRC competition providing the proving ground. In 2010, the best error rate was 28.2%. In 2011, 25.8% incremental steady progress. Then came 2012. Alex Kriski Alia Skeber and Goffrey Hinton submitted Alexnet trained on two Niveia GTX 580 GPUs. Top five error rate 15.3%. So we as as as years climb okay um the error rate declines. So years go error declines. Okay.
Uh next entry 26.2% a margin of nearly 11 percentage points that the entire field had not expected to see for another five or 10 years. Alex Net demonstrated several technique now standard practice uh really activation with the equation FX times equal max time O X which avoid the vanishing gradient and train six time faster than T drop regularization at P equals 0.5 on the fully connected layers data augmentation and GPU training delivering roughly four times Throughout the CPU training, the network has 60 million parameters across five convolutional layers and three fully connected layers.
The cascades of results that follow was extraordinary. VGET showed that matters. Google net introduces multiscales inception models rest nets. Uh he he eat a 2015 introducing connections with another equation h uh * x = x * x + x allowing gradient to follow to flow directly across layers and enabling 52 layers networks. Finally, image nets top uh top errors 3.57% below the estimated human error rate approximately 5%. The machine had learned to see better than we could and the rate had only just begun. Okay.
24:00So, as we move in in in in years, the years go up and the percentage of error, things are getting starting to get more perfect with the years uh that come. Okay. Now we're going to talk about the transformer revolution and the LL era uh sequence modeling before transformers. Give me one second here. Okay. All right. So the transformer revolution and the LM era sequence modeling before transformers language is inherently sequential. The dominant approach through the 2010 was the recurrent neural network. An RNN processes a sequence one token at a time maintaining a hidden state.
HT equals TH NH and the equation is W HH HTUS1 + W XH* X. The problem is back propagation through a multiple by the Jacobian of the hidden state. If the vectoral radius of W hh is less than one gradient vanishes exponentially is greater than one they explodes R and N's fails to learn dependencies across more than 10 to 20 time steps.
27:00LSTM's coach writers and shrine motor on 1997 introduced gating mechanisms are for gate gate. It has another equation, you know, f= o uh wf uh times uh h t -1 * h time xt times plus bf an input gate and sales state that acts as an information highway across many steps. This was a significant improvement but the fundamental bottleneck remain. The bottom bottleneck continues to remain. So as you can see this is like a uh we have we've been dealing with bottlenecks all our lives and eventually eventually there will be no bottlenecks and we're getting very close to that part. Okay.
Um but not attention in 2015 part partially addressed this. The decor could look back at all encoder hidden states and compute a weighted sum but the encoder and decorter were still RRNs. The sequentially dependency remain. Okay. In 2017, Fanwani Shazir Pararoric Jones Gomez Quaser and Poloskin published a paper with a deliberately provocative title. Attention is all you need. Their claim recurrence is necessary. I don't know. attention.
Attention is all you need. Just give me one second. Let me just open something for someone. What am I supposed to say? So um let's see in 2017 uh was sini chaser permer uhi Jones Gomez case here and puliski published a paper with deliberately provocative title attention is all you
30:03need and their claim uh recurrences is unnecessary. Attention alone apply in parallel across the entire sequence is sufficient. They were right. The fundamental operation is scale dot product attention. Attention. K V equals softmax. K Q KT divided V D K and V. Unpack these precisely. Queries. Q and keys K. Compute compility scores. The dot product qt give entry I J as the similarity between curry I and key pushing softmax into low gradient regions. Softman convert scores to attention weight summing to one. We take a weight sum of values. B every token simultaneously acts as a query, a key and a value. Every token can directly attend to every other token. No sequentially dependency, no vanishing gradient, no information and bottleneck.
Multi head attention runs H parallel attention operations with different learn projections. Multi head Q KB equals concat head and head and W O allowing the model to attend to multiple aspects context simultaneously in GPT3 the model equals 12,2838896 heads DK equals 128 points computational complexity is O time N2 times D in sequence length the quadratic scanning that makes long context expensive a flash tension by DAO et 2022 archives the same mathematical result with all times n memory by recording computation to minimize memory bandwidth usage positional encoding addresses the fact that attention is permutation variant.
The original senosio approach PO S2 I equals S I N time POS divided by 10,000 times at 2 I times uh divided D underscore model times period. Motor models use RO O rotary positioning embeddings or alibi.
33:00A full transformer block multi head self attention residual connection plus layer norm position wise feed forward network residual connection plus layer norm and quarter only bird process birectional decoder only GPT uses castle masking each token attend only to previous tokens virtually are frontiers models today GPT4 cloud GML Yama are decoders only transformers. Scoling laws and emergent cap capabilities. In 2020, Kaplan Mckandish Henigan and colleagues at Open AI published scaling laws for neural language models. Performance follows move power laws across many order magnitudes and we continue to get more equations for a fixed computer budget optimal location.
in parameters and in tokens. The chinchillaya paper Hoffman it l and deep min 2022 revise this ratios and and d should scale equally approximately 20 tokens per parameter. GPT3 at 165 billion parameters trained on a 300 billion token was undertrained by his standard Yama 2 at 70 billion parameters trains on two trillion token isa optimal GPT3 training cost an estimated 5 to 10 million dollars. GPT4 is estimated at $100 million or more.
The scallioning law paper gave AI labs a clear empirical rational for investing in ever larger training runs. If loss follows a predictable power law, larger models would reliably perform better with no hard still is invisible at current scales. emerging abilities uh way it uh 2022 documenting capabilities appearing uh discontinuously at threshold scales multi-step artifactic logical deduction analogical reasoning program synthesis chain of thought reasoning emerge around 100 billion parameters in context learning emerged at the few billion the interpretation is condensed Schaffer Uh 2023 argues emergencies emergence is an artifact of discontinuous metrics but the patriarchal phenomenon is not scanning relability produces new capabilities often unanticipated section uh next section instruction toning nhf a pre-trained language model predicts The next token it has no concept of helplessness. The transformation to a
36:09useful assistant required two stages. First a supervised fine-tuning on a human written prompt response demonstration. We algorithm uh 2021 show instruction tune models generalize zero shot to instructions not seen during finetuning outperforming much larger space models. Um second reinforcement learning from human feedback RLHF three stages collect comparison data. Human raiders compare response for given prompt. Train reward model R O of those preferences using the objective mass.
Then optimize the language models against the reward model via PO with the KL differences penalty. So is max uh e * r o * x comma y minus uh b * kl and pi * x parallel tf time x. The KO penalty prevents the model from drifting too far from it supervised fine-tuning behavior preventing reward hacking. The PO clip objective limits excessively large policy updates. The instruct GPT paper show a 13 billion parameter RLHF model was preferred by human evaluators over the raw 175 billion parameter GP3 on the vast majority of prompts. Alignment training dramatically improve perceived quality even when it reduces raw parameter account capabilities and alignment are not in fundamental tensions. Uh constitutional artificial intelligence anthropic approach adds a set of written principles to the process that model critiques and revises it opens output accordingly to those principles. AI feedback R L Aif scales better than pure human evaluation. Shat GPT launched on November 2022. 1 million users in 5 days. 100 million in two months. No consumer technology in history have ever grown that fast. Okay.
So the multimodal models and scientific uh AI. Hey, how you doing everybody on
39:44Okay. Um the current frontier multimodel models and scientific artificial intelligence the transformer architecture generalized beyond text any sequence of tokens will do image patches audio spectral frames video frames protein residues. This architectural university has produced multimodal models that process and generate content across modalities in an integrated way. Flip rap for algorithm at open AI on 2021 trains images and text encoders jointly using contrastive learn contrastive learning. Maximize cosign similarities of machine image text pairs while minimizing non-matching pairs. The result is a shared embedding space where images and their descriptions are geometrically close. Zero shot clip match fully supervised. Next uh restnet 50 on image net without a single label image. The rich semantic structure of language alone provides sufficient supervisory signals.
The future models generate images by learning to reverse anomous process. The forward process and there's another equation uh xt = va * x uh 0 plus v uh 1 - 8 to the T and E progressively adding guine noise. The model learns to predict the noise and at reference start from pure noise and interjectively den noiseise conditions on a text prompt.
42:03Classifier free guidance higher W gives image more faithful to the prompt. Latin diffusions minus stables diffusions minus operates in b a compressed latin space four to eight times more efficient than a pixel space diffusion. Um alpha fold to uh jumper eat algorithm nature 2021 solved the protein folding problem using the e evo former architecture. It process multiple sequence alignments related sequences from across evolutions along with pairwise distant features updating both in a quadruple way. The intuition evolution performed a massive natural experiment and co- variation patterns across species and code threedimensional structures constraint TM score of 0.92 on CAS 14 the data the database now contains predictive structure for over 200 million proteins essentially ever known protein the implications for drug discovery are most significant scientific achievement of this century. So with these equations and all these algorithm, the alpha fall and the jumper algorithm, we're going to have uh more achievements on on on the scientific uh area of on this century. Okay.
Uh, Agentic AI autonomous systems. Okay. This is what is coming next. Um, um, we starting to see those uh, identic AI autonomous systems. We start seeing see vehicles driving themselves. Boats will drive themselves. Airplanes will drive themselves. Everything will drive themselves. Okay. Robots will walk by themselves. Uh, a language model that answers questions is impressive. A language model that plans a sequence of actions used to observe results and revise its plan in pursuit of a goal is something qualitatively different. The react loop ya algorith 2022 interces and actions invocations the model reasons about what to do next.
You know it generates a structure tool calls or receive the observation incorporates it and continues and continues tools used via function called structure JSON schemas define variable
45:00tools the model generate calls and a sandbox execute them. uh results return observation code execution the motors write patent uh the interpreter runs it stands out and stay there return as the next observation multi- aent system decompose task across specialized agents operating in parallel pipelines orchestrators agents architectures a central agent deco composes the task and delegates and relability compounds across agents Five agents uh each at 90% per task give only 59%'s overall success.
Remember these are new things sets as we move forward the overall success 59% start will start coming down as well. Okay. Uh context window managements and memory architecture require explicit engineering. Uh the retrial augmentated generation grounds models in real data documents are encoded as dense embeddings stored in vectors databases pine cone weate chroma and pg vectors and retrive at inference time by co similarity search retry documents are injected into the context windows inside the query advanced rank pipelines at query rewriting Epotellically document embedding, reranking and recusive retriever to improve quality and reduce hallucinations.
The current model landscape and benchmarks GPT4 from open is an estimate mixtures of experts architectures 128,000 tokens context windows top performance of month human evaluation and MMLE GBD4 meaning integrate text vision and audio end to end rather and uh top model of pipelines claw 3.5 sonnet forthropic state-of-the-art on SW bench resolving approximately 40 to 50% of real GitHub issues strong instruction following constitutional AI alignment and active mechanism interpretability research Gemini Ultra from Google deep mind first model 2X6 human expert performance across All 57 MNLU subjects natively model from the ground up.
Show the 57 MMLU subjects
48:05are abstract algebra, anatomy, astronomy, business ethics, clinical knowledge, college biology, college chemistry, college computer science, college mathematics, college medicine, college physics, college security, conceptual physics, ecomtrics, electrical engineering, elementary mathematics, formal logic, global facts, high school biology, high school chemistry, high school computer science, high school European history, high school geography, high school government and politics, microeconomics, mathematics, microeconomics, physics, psychology, statistic, US history and world history, human agent, human and sexuality, international law, Jewish prudence, logical classes, machine learning, management, marketing, medical genetics, ICS, miscellaneous moral disputes, moral scenarios, nutrition, philosophy, prehistory, professional accounting, professional law, professional medicine, professional psychology, public relations, security studies, sociology, US foreign policy, verology, and world religious. So, is one of these are your jobs? Know that you are will be replaced and you are currently already uh will be replaced by artificial intelligence in the next 10 years, five to 10 years because um that's where we are right now.
Um the Yama 3 from meta 70 billion open weight parameters competitive with significantly larger closed model. The existence of powerful open way model has profound implication from research accessibility fine-tuning and the competitive dynamics of the industry benchmarks MLU text knowledge across 57 subjects. the subjects that I just mentioned. GBD4 scores approximately 87% human expert and approximately 89% random baseline 25% human evaluation measures called generations. So uh GPT4 and now we are in GPT 5.2 and we're going to be continue moving uh up as we continue moving our models.
Um GPT4 scores approximately 87%. Okay. Uh and human expert approximately 89% that's B+ on all 57 subjects. Okay. Um humans are expert on few of those subjects. This is scoring overall
51:0389% on GPT4. Now we are on GPT5. So what happens every time that we move from one model to a new model, the model goes up and and and and the percentage of uh the human experts continues to go up. Okay. So so what was B+ becomes a minus and After a minus we comes A+ and after a plus comes super intelligence. Okay. Uh human evolation measure host generation DBT4 achieve uh pass uh at one of approximately 67%.
Uh subswe measure practical software engineering capabilities. Frontier model solve 40 to 50% of verified task. A arc uh AIG AGI designed to require genuine abstract reasoning was below 20% for all frontier models until uh Mini3 achieved 87.5% at high compute. Critical caveat benchmark uh performance and real world utility are imperfectly correlated. Goodart's law applies a measure that becomes a target cease to be good measure. Treat benchmarks numbers as signals not ground truth. Okay.
Uh so so the benchmark numbers are just signals. Okay. So and the signals are that we continue to move models and and the models and the computers continue to evolve and continue to learn and continue to get better. Um what they failed last year and they already learn it. They're not going to commit the same error. So they're going to continue to move forward. Uh artificial intelligence in production infrastructure and inference engineering that's the next subject.
Training frontier models require thousands of GPUs in tight synchronosity. Distributed training strategies. Data parallelism replicates the model and split the data batch. Model parallelism splits the model itself across devices when it does not fit in a single GPU's memory. Tensors parallelism splits individual matrix operations. Pipeline parallelism splits into layers into stages. Numerical precisions uh FP32 for stability. FB16, BF16 for training
54:02efficiency, int8 and ENT for quantitization for inference cost reduction. The KV cache store keys and value projections from all previous process tokens enabling efficient autogressive generations without reprocessing the full context at each step. Imagine managing KB cache memory across thousands of concurrent users require continuous batching and cach eviction and and carefree memory management. Speculative decoding uses a small draft model to generate a candid tokens that the large model then verifies in parallel achieving two to three times throughout input improvement. The co the cost of latency profile of LL inferences measures in tokens per second and dollars per million tokens is a central engineering constraint shaping what applications are feasible. A well quanticized 20 billion parameter open weight model running locally is competitive with club with cloud API calls for many applications at fractions of the ongoing cost.
So when when we're talking about F-32 for stability, FP16 and BF616 for training efficiency, INT8 and ANT4 quantization for inference cost. We're talking about how numbers are represented inside of the GPUs and neural networks. Neuronet networks are just large collections of matrix uh multiplications matrix or multiplications multiplying and adding numbers and billions and trillions of times. Okay. Um one second. So hello hello everybody. How you doing?
So what is a numeric numerical precision? Computers do not store real numbers like humans write them. They they sort approximations using binary flotation points or integer formats. The more bits used to represents a number the more precise it is. The larger range of values it can represent, the more memory it consumes, the lowers
57:00it may be compute. Precision equal tradeoff between accuracy speed memory and cost. So your binary 01 that's what we're talking about here. Okay. FP232 uh and 32-bit floating point is the full precision. One bit for sign uh 8 bit for exponents and 23 bits for mantisa. This give uh seven decimal digits of precision, very wide dynamic range and very strong uh numerical stability. Why we use FP32? Because training neural networks involve uh back propagation, very small gradient values and accumulating tiny updates or millions of steps. If precision is too low, gradients can vanish to zero. Um, and overflow to infinity becomes unsustainable.
Hello. I go I go later on um I go later on to to to co-host and take all the invites. Okay. Uh the downsides four bytes per parameters slows the GPUs compared to low precision for a seven seven billion parameter model 7 billion * 4 bytes equals 280 GB just for weights before optimized states that's massive. Uh the FB16's half precision 16 bit floating point. Uh that's what FP16 means. uh one sign one bit five exponent bits 10 misa bits this means much less precision more much smaller range two bits per parameter have memory of um uh floating point 32 huge advantage uh modern GPUs Nivea tensor cores excuse me are optimized for um floating point 16 math two times memory savings two times The output increase the the problem smaller exponent range uh move to gradient can underflow training can become unstable. The solution is a mixed precision training. In mixed precision for pass in floating point 16, gradients computed in floating point 16 master weight stories on floating point 32 lo scaling prevents underflow. This preserves stability while doubling speed. So BF16's brain floating point uh the BF float 16 is different from floating point 16s. It uses one side bit uh eight exponent bits same as floating point 32 and seven mantis sub bits meaning same dynamic range as floating.32 uh less precision in detail two bytes per parameter. Why this is powerful?
1:00:03Because most Neural networks instability becomes from exponents overflow underflow no for mantisa precision. Um ring floating point 16 keeps the wide range but reduce detail precision that makes it more stable that uh floating point 16 lately as fast easier to train large models with most models LLM training uses uh brain floating 16 uh while lower precision is important training a frontier model thousands of GPUs, weeks of month of compute tens to hundreds of millions of dollars. If you can cut memory in half, double the output and reduce energy cost, you change the economics of AI.
Precision is not a math choice, is a financial decision. uh int8 uh 8 bits quantitization inferences after a model is trained we usually don't need full precision during inferences no back propagation no ranging accumulation just forward pass we can compress weights from floating points to integers int8 means 8 bit ingers one per parameters four times smaller than uh floating point 32 times smaller than floating point 16 brain floating 16 to do this we apply quantization original weight w scales times in into eight value the model stores integer weight scale factor when running in8 times int8 accumulates rescales Modern GPUs support far int8 matrix multiplications. Result two minus four time faster inference. Massive memory saving lower CL cloud cost.
Um the inch for 4bit quantization aggressive compression uses four bits per parameter 0.5 bytes per weight and eight times smaller than uh FP32. This is extremely compact. Use it for running elements locally, edge devices, consumer GPUs and model hardware. Examples, uh 70B parameters, uh FP32 280 GB, BF16 GB, NT8 70 gigabytes, and NT4 35 gigabytes. As you can see, gigabytes
1:03:00start going down. So less gigabytes um you have uh less cost on the server side uh on the equation. Okay. Uh now suddenly consumers GPUs can host large models. Cloud cos dramatically.
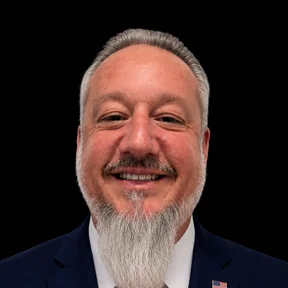
About Victor J. Rosario
Victor J. Rosario is the Residents-First candidate for Miami-Dade County Mayor 2028. A U.S. Coast Guard veteran, entrepreneur, technologist, and artist, Victor brings a track record of building real solutions — from AI tools to campaign policy — that serve Miami-Dade's 2.8 million residents.
Learn More About Victor